Infinite Mac: Snow and A/UX #

tl;dr: Infinite Mac now uses a custom WebAssembly build of the Snow emulator to simulate many early 68K Macintoshes. Snow is a more capable emulator; in addition to classic Mac OS, it is now possible to run A/UX (Apple’s late ’80s UNIX/Mac hybrid).
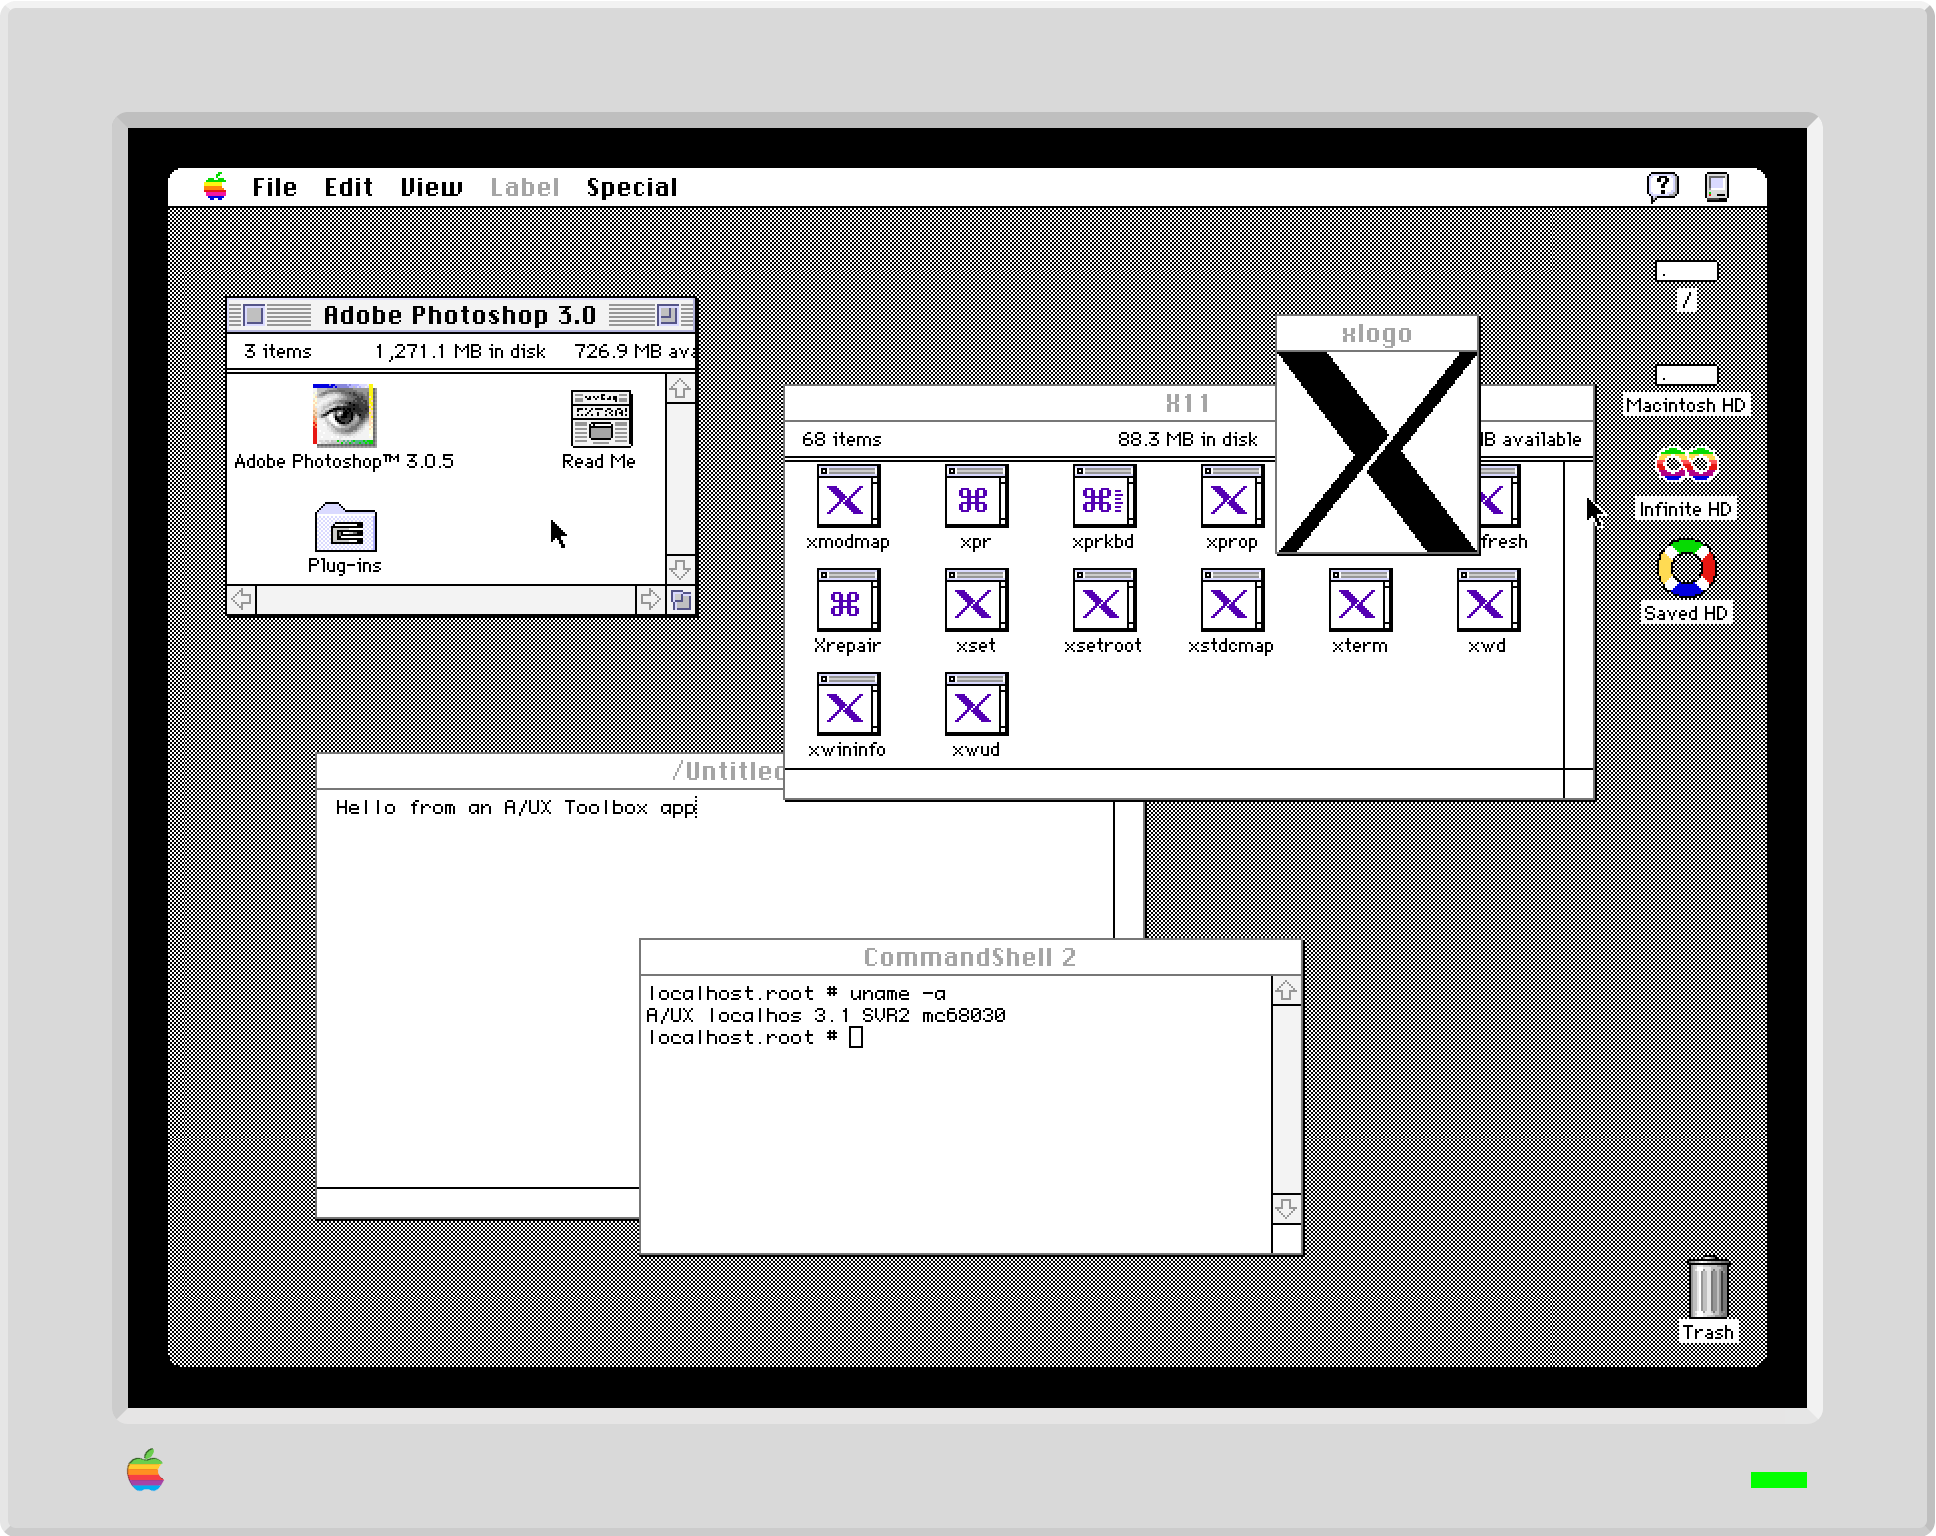
A/UX 3.1 running inside Infinite Mac, showing the Finder opened to a Photoshop Window, the xlogo X11 program, and a command shell.

Snow

Since its launch, all of the early (pre-System 7) instances on Infinite Mac have been powered by Mini vMac. I’ve previously discussed how it’s a somewhat idiosyncratic and seemingly abandoned codebase. While the core emulator works well enough, I had a long list of features for deeper integration into the site (and bugs). I did not relish the thought of diving back into a sea of cryptically named functions and C preprocessor tricks. Separately, “learn Rust” had been on my wishlist, but I never had a project in mind for it.

It was thus fortuitous that Snow was released late last year. It’s an emulator that covers the same era1 as Mini vMac, with a focus on accuracy. It also happens to be written in Rust, and has an active maintainer and community. I set out to bring up Snow as a new emulator core inside Infinite Mac, with the goal of eventually replacing my use of Mini vMac.

Snow is a well-structured codebase; there’s already a separation between the core and the native frontend. It was pretty natural to add a new crate that hooked up the core to the Infinite Mac abstractions for video, input, audio, disk images, etc. For file I/O and audio, Snow didn’t quite have the flexibility I needed, but it was feasible to add a layer of indirection. The maintainer was open to merging these changes; my fork is mostly Infinite Mac-specific work, and thus easy to keep up to date.

The flipside of Snow being a more accurate emulator is that it also replicates the limitations of early Mac hardware. For example, the original Mac 128K only had an internal 400K floppy drive, and a connector for attaching an external one. But there was no first-party hard drive (at least, not without hacks) and third-party ones sound finicky2. Mini vMac did not quite operate at that level (it instead patches the ROM and relies on that custom driver) and thus it was possible to “cheat” – I had simulated an “Infinite HD” for it with 1.4 MB of installed software, even though that was anachronistic3.
Infinite Mac emulating System 1.0 on the Mac 128k, showng the message 'Please insert the disk Write/Paint' with the floppy drawer open.
Disk swapper’s elbow, now in your browser
Mac Missiles created by Avadis Tevanian, Jr. (who later became Apple CTO)
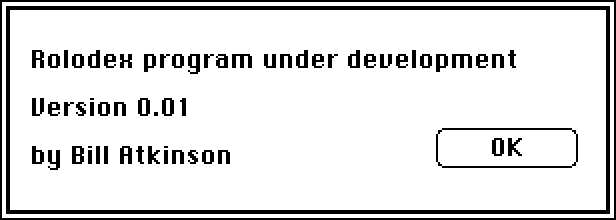
Rolodex created by Bill Atkinson, presumably as a side-project
Some familiar names in early Mac software about boxes

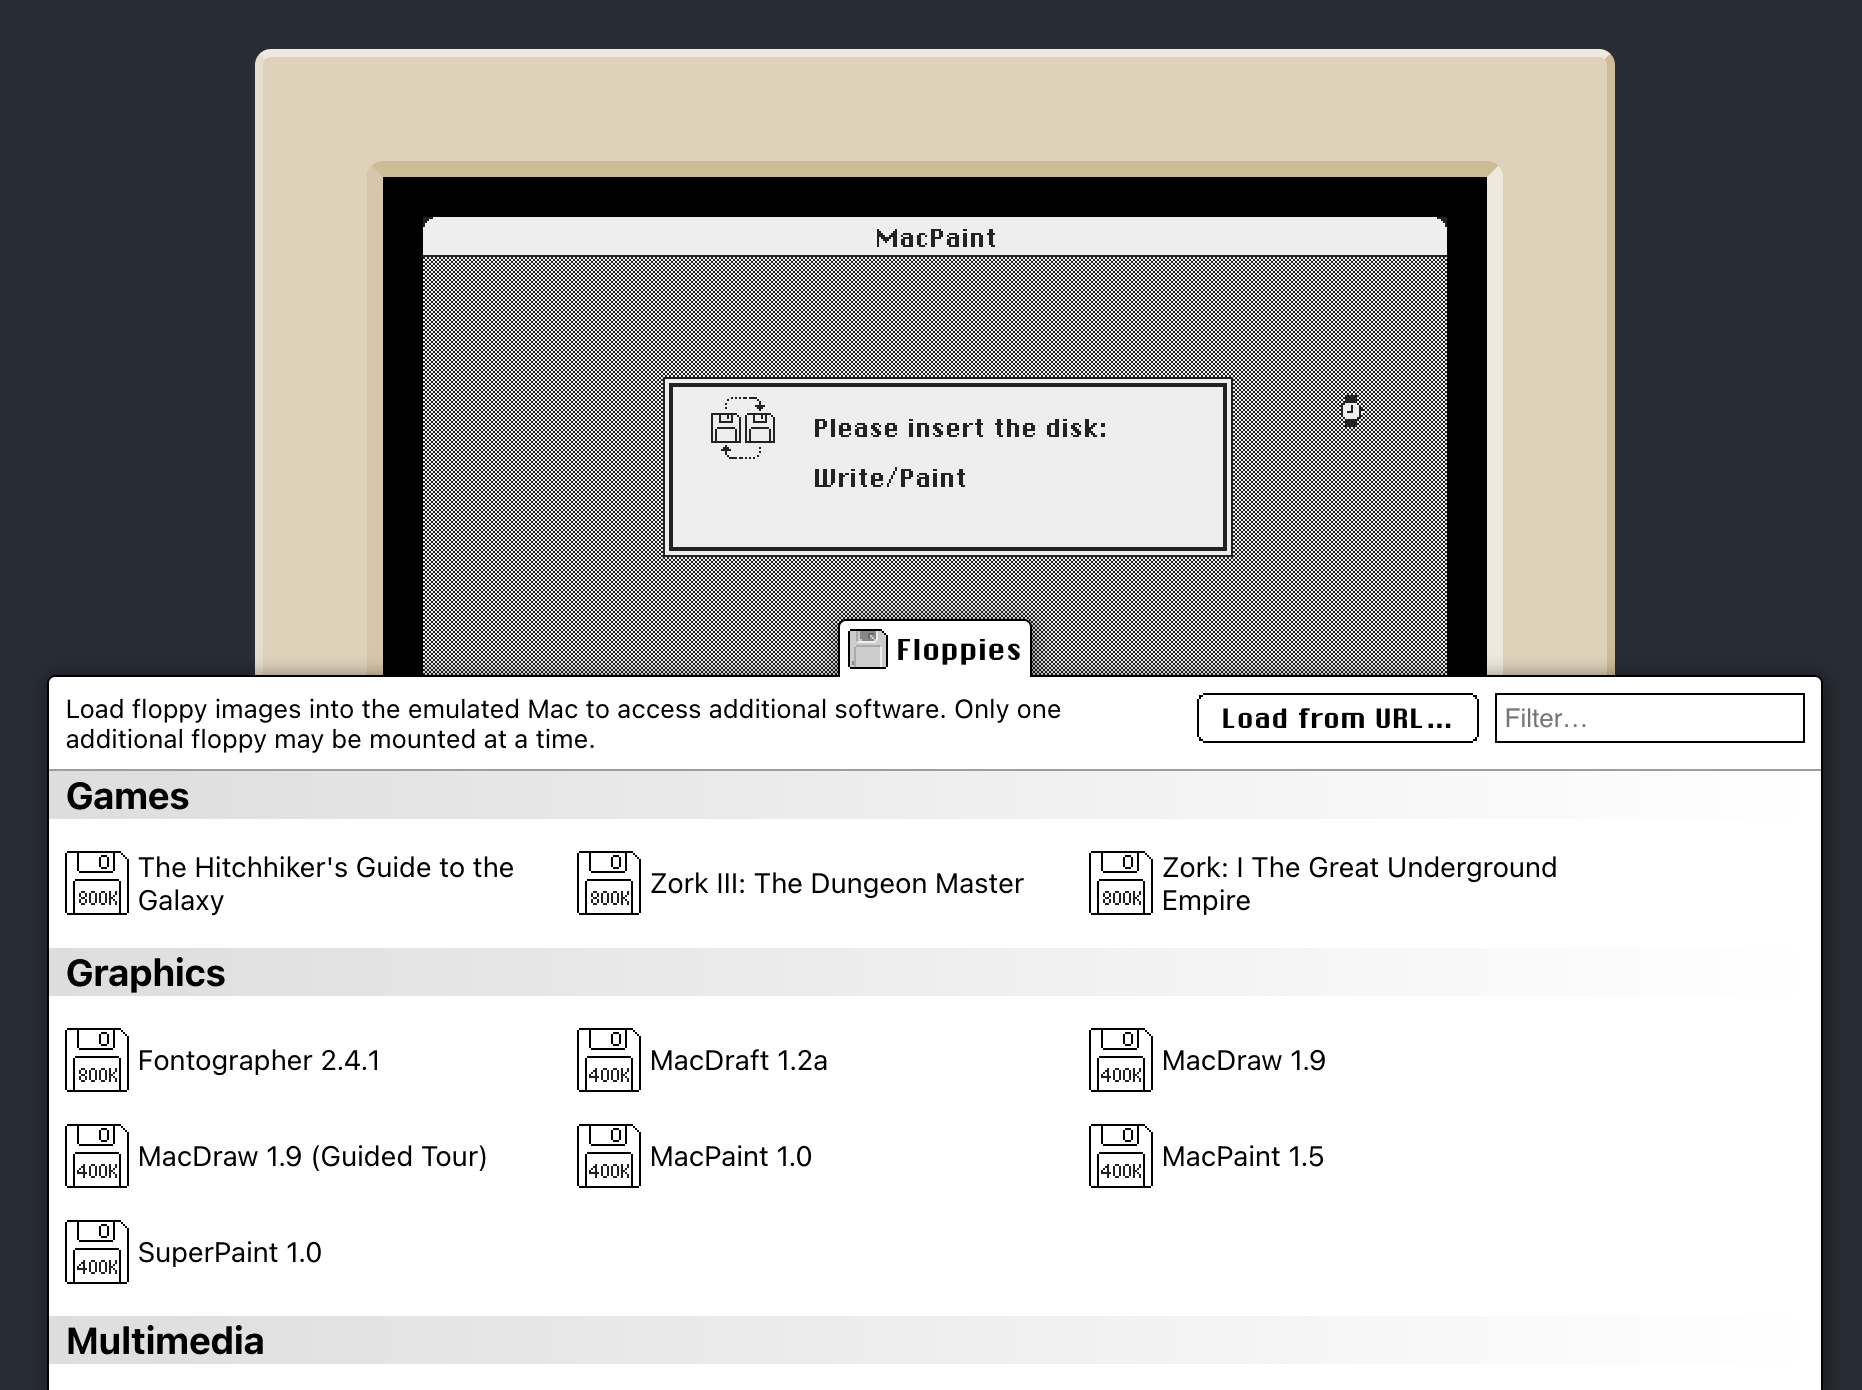
In lieu of a hard drive, I ended up extending the CD-ROM library feature with a “Floppies” companion. It draws upon the Internet Archive (especially the Moof-A-Day collection) and the Macintosh Garden to showcase early Mac software. Unlike with CD-ROMs, the disk images are small enough that it’s worth it for me to host them – it both improves reliability and allows me to preprocess them, to handle compression and other edge cases.

Despite the Mac having a reputation of not having a lot of software, it was still impressive just how much there was released even in its first couple of years of its existence. I’m sure I’ve missed including some classics, but I’m happy to add more if you let me know.

Additional changes were required to handle Snow’s verisimilitude. MODE32 is now available to allow the IIcx and other non-32-bit-clean machines to actually address more than 8 MB of RAM. I had to make sure that a CD-ROM driver was installed on all disk images, otherwise CDs could not be mounted. Similar to the hard drive situation, I had been relying on Basilisk II’s ROM patching for this support.

The most complicated change involved teaching the OS to handle dynamic screen sizes and color depths. Snow emulates real NuBus graphics cards (unlike Mini vMac and Basilisk II’s virtual screen drivers), and they would default to black and white. The configuration is driven by a scrn resource that’s stored in the System suitcase of the boot disk. Its contents need to be dynamically generated based on the chosen screen resolution, so my normal approach of doing this at disk image building time (which is what I do for Stickies text) would not work. I instead leave a placeholder entry on disk, track its location, and overlay at runtime the values for the current screen parameters.

Snow brings some additional capabilities too, so all this work was not just to maintain the status quo. It has built-in support for the BlueSCSI Toolbox protocol, allowing file sharing with the host. This means that it’s possible to have a variant of The Outside World drive, though not as slick as Basilisk II’s virtual folder structure. It also emulates a SCSI-based printer, which I’ve hooked up to Infinite Mac too – you can now “print” to export graphics as downloadable PNGs. There’s also a long tail of Mac features you can now experience, such as booting from ROM with the Mac Classic. Finally, Snow aims to more accurately replicate the speed of the machine, though if you get impatient there is an “Uncapped” speed setting.
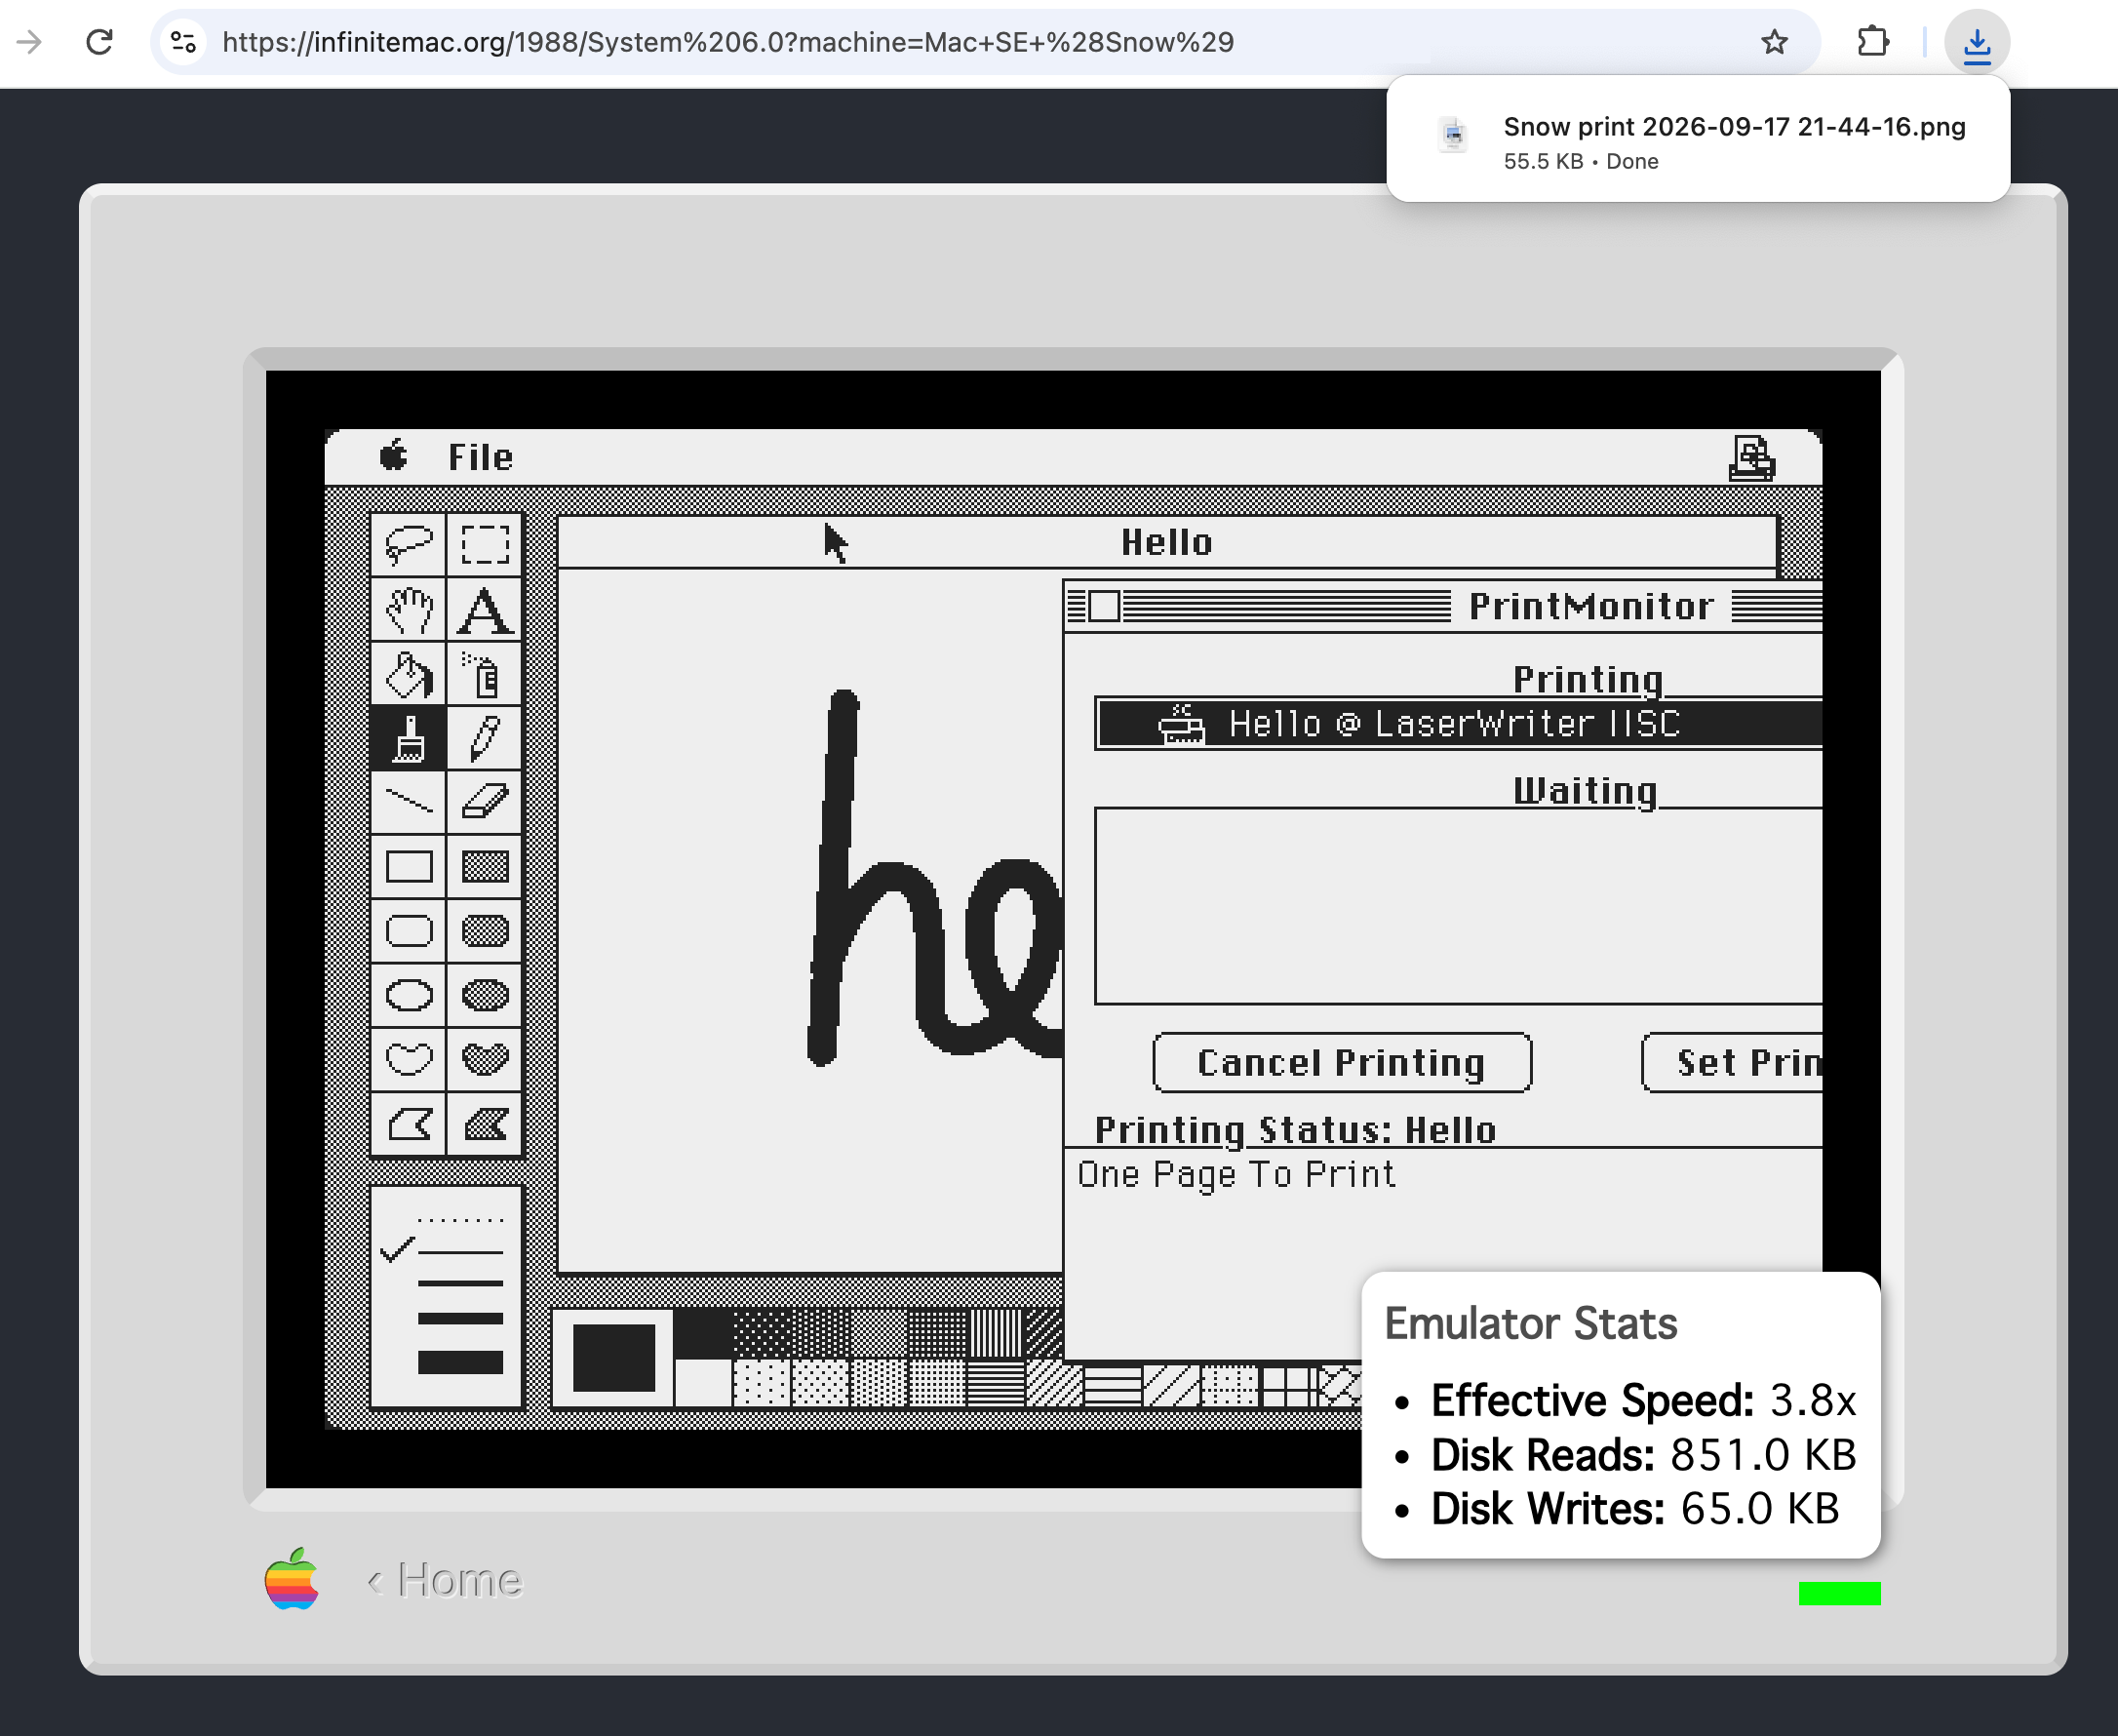
MacPaint "printing" to a PNG file inside the Snow emulator on Infinite Mac

A/UX

A secondary reason for adopting Snow was that it seemed quite likely that it would be able to run A/UX, Apple’s alternate UNIX-based OS from the late 80s and early 90s. While Shoebill was also an option I had considered, I didn’t relish the idea of incorporating yet another frozen-in-time emulator4 just to run one OS. Sure enough, a few months after I’d started the port, Snow 1.5 was released, bringing A/UX support.
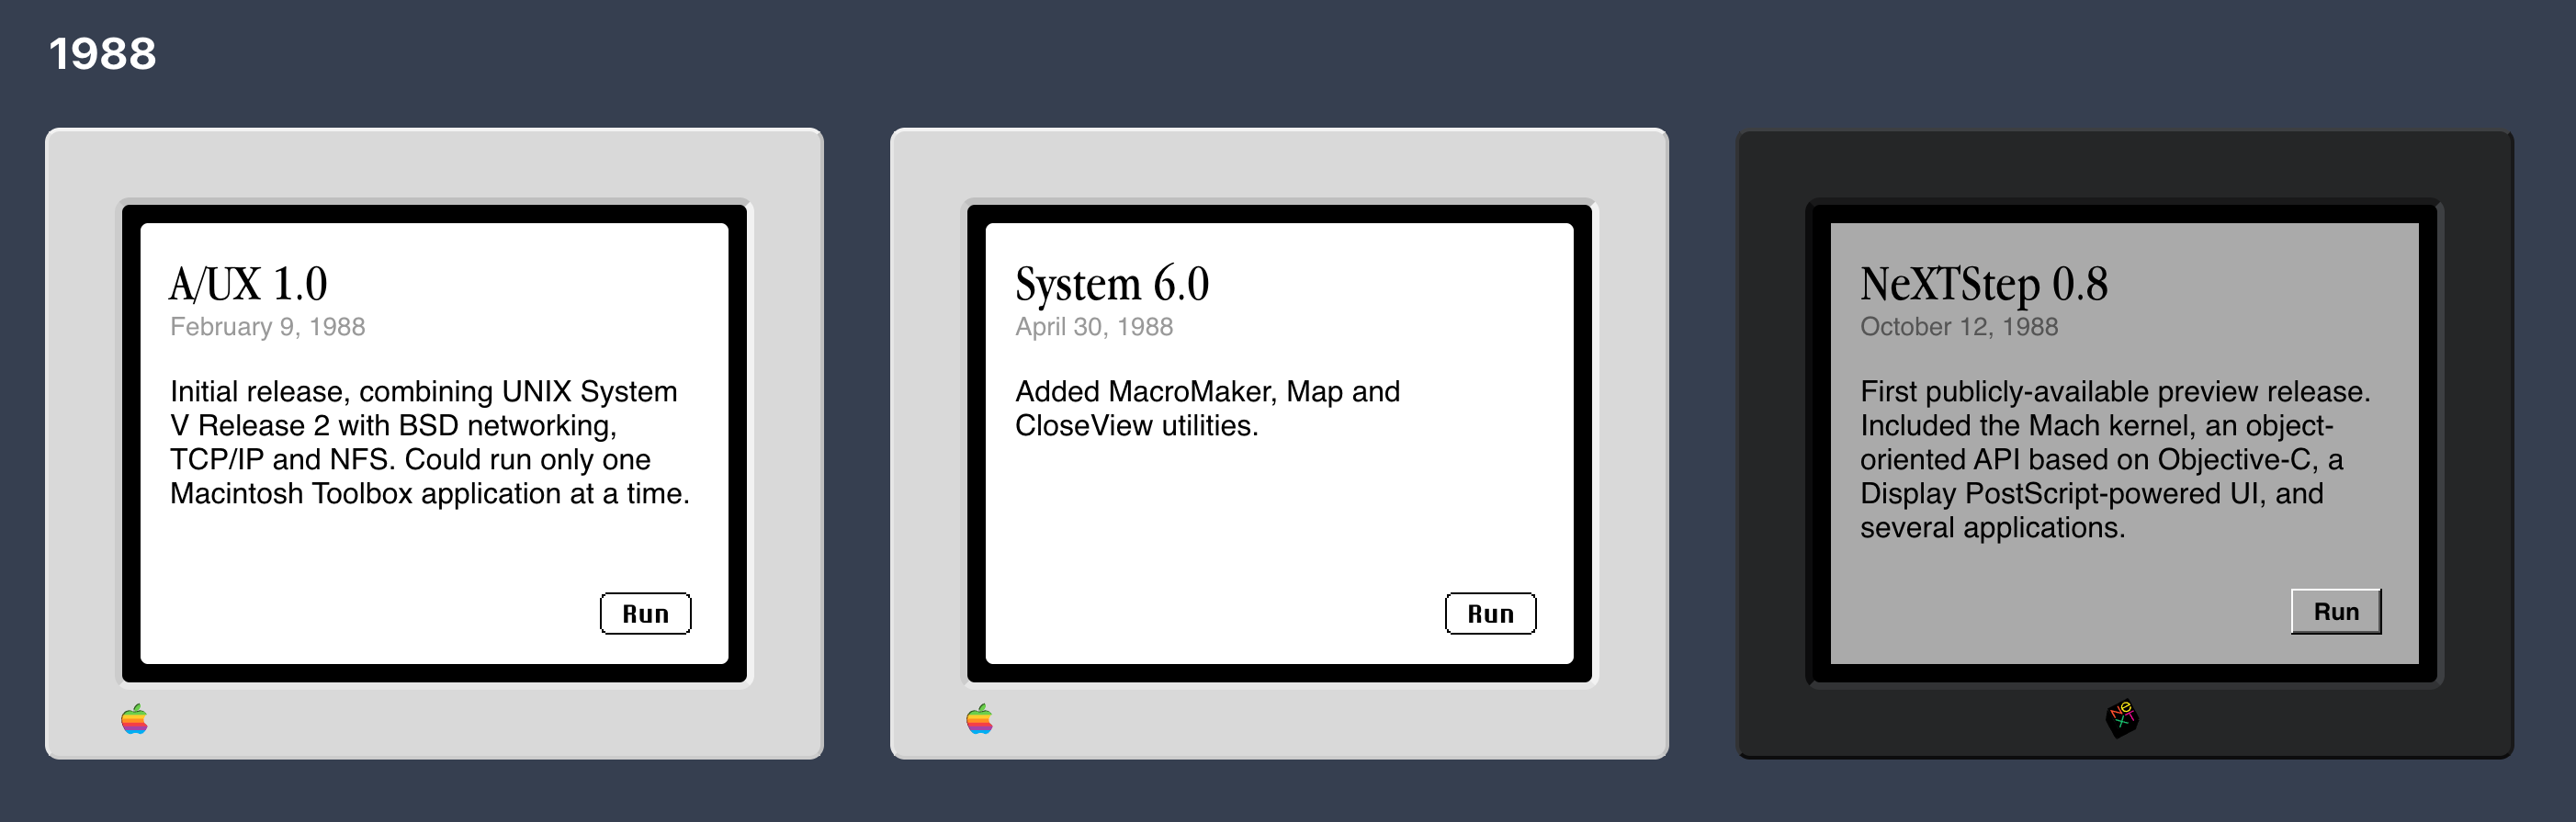
1998 saw the release of A/UX 1.0, NeXTStep 0.8, and System 6.0
1988: The Year of UNIX on the desktop (and System 6)

A/UX mostly just worked – it was a matter of adding additional system images and categorizing them appropriately. Much like early releases of Mac system software and NeXTStep, it’s hard to find original installation media – 1.0 is still MIA and 1.1 was only recently archived5. The OS installations are most fresh-out-of-the-box, though I did end up making some tweaks to make the booting marginally friendlier.
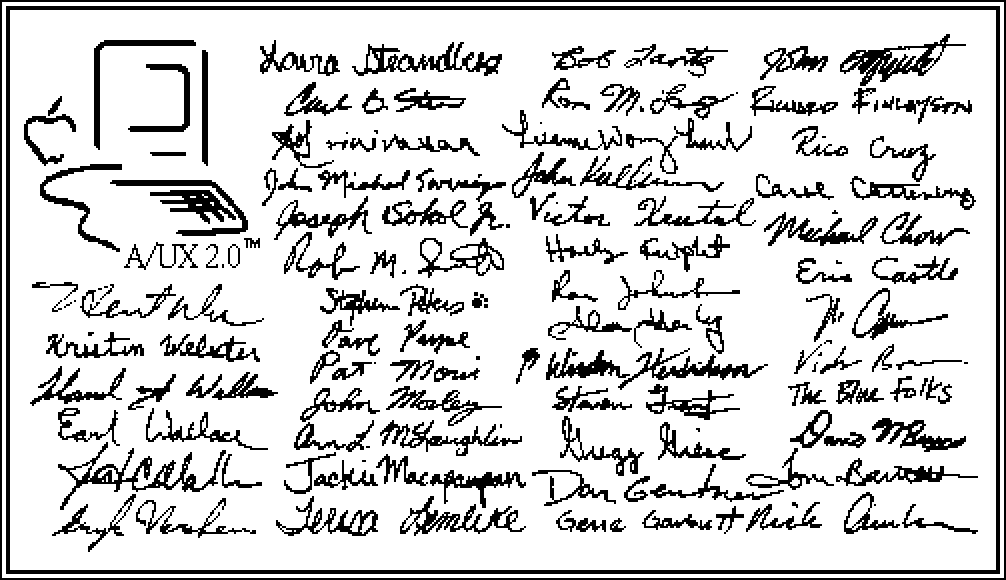
A/UX 2.0 about box, showing the signatures of all those woho made it
It’s nice to be able to sign your work

This is my first time actually using A/UX, and it generates some cognitive dissonance. On one hand, it’s a classic Mac, with a Finder (at least starting with A/UX 2.0) and other familiar trappings. On the other, it’s a UNIX system, with a terminal and other things that engender “It’s a UNIX system! I know this!” feelings. But the UNIX is old (I kept typing vim instead of vi, and really missed tab completion) and feels quirky at times6.

The combination of the Mac GUI and UNIX does feel powerful, though the integration is much clunkier than what was ultimately achieved with Mac OS X, more than 10 years later7. The seams between the two (or even three, if you count X Windows-based UNIX GUI programs) worlds are pretty visible. There was an attempt at bridging the gap, via A/UX Toolbox programs, but it doesn’t appear to have been commonly used. For example, only the X Windows version of Mosaic was available, as opposed to a best-of-both-worlds A/UX Toolbox take on the Mac port. And in the other direction, A/UX did include a Commando mode that added a GUI to common command-line tools. However, it didn’t solve the fundamental issues of discovery in a CLI (you had to know the name of the command to invoke Commando for it).
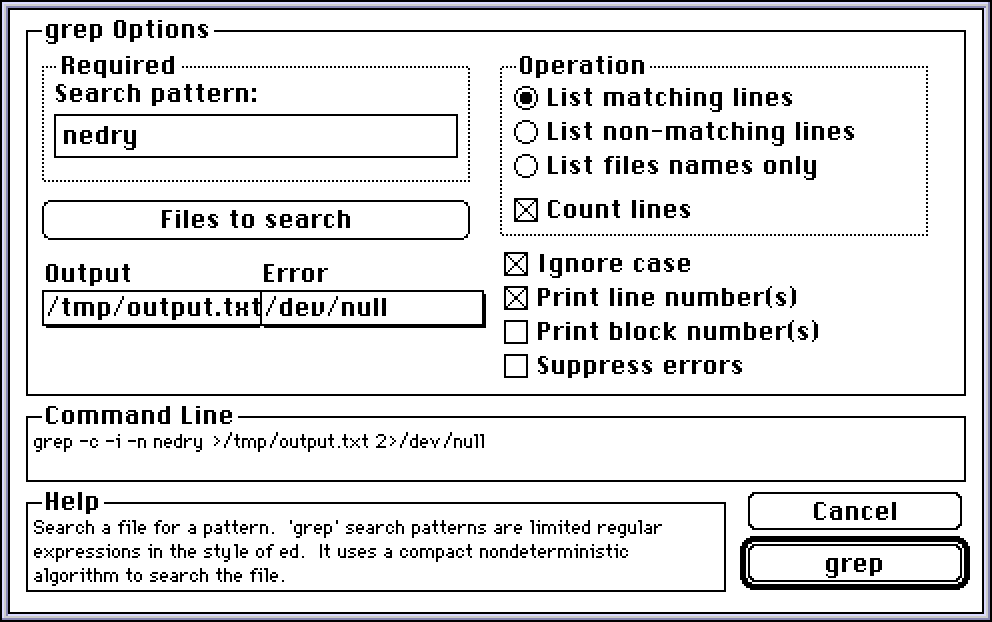
A/UX Command dialog for the 'grep' command, showing some of its options as checkboxes and radio buttons
Commando output for grep – curious what it would have been for git

While later versions of A/UX could directly mount HFS disks, it still required the use of UFS for booting, which made integration with Macs (and their resource forks and metadata) clunkier. The solution was the AppleSingle and AppleDouble formats, which is the one part of A/UX that lives on: AppleDouble is still used in .zip archives in modern macOS.

If you’d like to learn more about A/UX, this post on Virtually Fun and this one on The Long View are worth reading – they both describe the story and have some ruminations as to why it was a dead end. There’s also the A/UX FAQ and this software archive.

Learning Rust

As for my “learn Rust via the Snow bring-up” goal, I did not achieve it, at least not in a traditional way. I got the book, made my way through the first few chapters, and developed some familiarity with Rust concepts. But I couldn’t quite sustain the interest in learning all of the mechanics, especially with Snow being a relatively mature and complex codebase, and my needs being simple, mostly glue code.

This was around January, shortly after coding agents had hit an inflection point. I figured this would be a good test case: did I need to learn the syntax and other basics, or could I skip straight to the interesting parts? While the agent (Claude Code initially, Codex nowadays) knows Rust a lot better than I do, I still felt like I was adding value. Its first attempt to get things to build under Emscripten involved littering #[cfg] checks everywhere. I had to direct it to use stubs, and generally prioritize diff size and maintainability. Similarly, to actually get to the boot stage, I had to draw on past experiences about draining sound buffers.

For the most part, I’m fine with where things ended up – I still understand the generated code, even if I wasn’t the one entering it in. Developing more familiarity with the Rust ecosystem also allowed me to use it in other places: it now powers automatic decompression of disk images inside of StuffIt archives. I still have a lot to learn too, and it’s mostly on me to decide how much I want the agent to be in teaching vs. do-it-for-me mode.

I’ve also found agents to be helpful when debugging, much like the experiences of Linus Torvalds and Arbee8. With emulators there are many things to keep track of (host, emulated CPU, MMU, devices, guest OS/kernel, guest processes, etc.), and agents can churn overnight doing an instrument/run/get a breadcrumb/repeat loop. Getting to a smoking gun is not as satisfying as doing it by hand, but I don’t always have the time or energy for it.

Other Site Improvements

The agent-assisted debugging enabled me to make some more fixes to DingusPPC, and the Mac OS X Public Beta now boots correctly (you can admire the courage to have a non-functional Apple logo in the center of the menu bar). I also made some performance improvements (DMA is good for emulators too) and implemented CD-ROM insertion for that emulator, allowing the CD-ROM library to work for the more modern PowerPC machines that it emulates.

There were also a bunch of quality-of-life improvements: an on-screen keyboard to allow obscure keys to be entered, a cleaner way to open Infinite HD at startup (without littering aliases to it), support for client-side (CORS) fetching of external disk images, and even a fix for a longstanding SheepShaver issue.

As for what’s next, I’m debating between breadth and depth; we’ll see what sparks joy.

  1. Early Motorola 68K-powered Macs, though Snow keeps increasing its time horizon. 
  2. Third-party hard drives were also rare enough that I’ve seen no attempts at reverse engineering them. This thread is converging on enough information about the Tecmar Mac Drive that it may be feasible now. 
  3. Amusingly this then ended up in David Pogue’s Apple: The First 50 Years book. Hopefully the screenshots within it are not treated as gospel in a future The First 100 Years edition. 
  4. The author is alive and well, but there is a conflict of interest – the author works at Apple now. It is amusing to think that it is Apple conflicting with itself. 
  5. And it’s not much fun to install from scratch. 
  6. Why does the manual encourage you to run sync;sync;sync as part of system shutdown – would one sync (or two) not have been enough? 
  7. Or what NeXT had around the same time, another way in which it was ahead of its time. 
  8. A MAME maintainer working on Mac support – see also their AI tips

Sierra MCP Gateway Dev Diary #

I wrote a post for the Sierra blog about building our internal "MCP Gateway". An early draft was was formatted as a development diary; we ended up abandoning that approach due to its length and lack of "catchiness". But I thought it would be fun to preserve for posterity, so I'm archiving it here.

Context is the lifeblood of internal agents - even the best model in the most full-featured harness will struggle to produce a better-than-mediocre result if it knows nothing about your company, team or project. Access to internal data was thus a crucial step in enabling Sierra employees to effectively use agents to get their jobs done. In parallel with building out the Pinecone internal agent system, this spring we also created a “gateway” service to allow safe and comprehensive access to the SaaS products and internal systems that Sierra runs on.

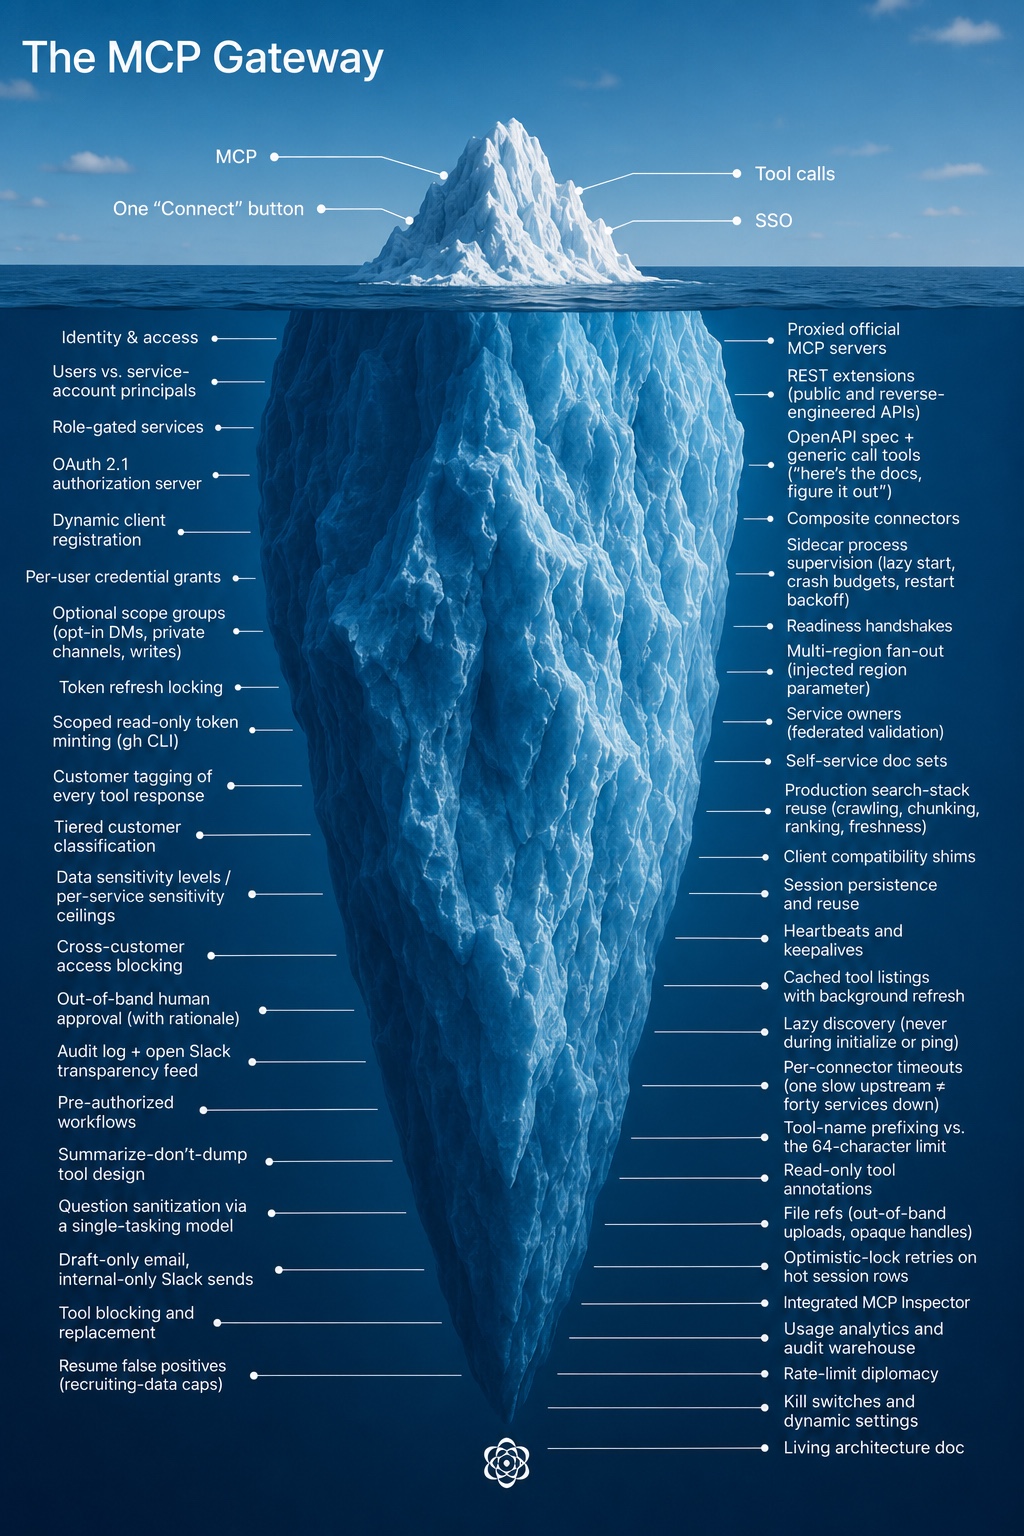
The gateway is built on top of the Model Context Protocol (MCP), the industry-accepted way of exposing systems to agents, giving them “tools” to read and act with. Released in late 2024 and exploding in popularity in 2025, MCP is a “mature” (some might say “boring”) technology by AI industry standards. One might thus assume that building an MCP gateway would be a straightforward project. However, it ended up having surprising depth, joining the flotilla of icebergs that Sierra has accumulated.

Iceberg entitiled 'The MCP Gateway' with 4 things above the surface and 40 below

To convey the kinds of problems that needed to be solved and give a sense of AI-enabled development within Sierra, we thought it would be interesting to present a “development diary” of how the MCP gateway came to be. It captures the work of roughly one-and-a-half engineers who built the gateway, sometimes working full-time and at other times treating it as a background task.

Week 1

Services: 1 · Weekly users: 1 · Pinecone-authored commits: 0%

The AI acceleration team has the expression “grabbing the lock”, meaning roughly “I claim ownership of this area, please check with me first before doing something that might affect it.” With every individual engineer being that much more productive, it behooves us to avoid coordination overhead where possible. It also avoids the temptation of sending off a coding agent on a side-quest to implement an idea you might have had (in case that idea is at odds with the lock holder’s broader vision).

We thus grabbed the lock on the “connect agents to data” problem, both within the team and the company as a whole. By this point everyone at Sierra wanted their agents connected to something: sales to the CRM, recruiting to the applicant tracker, engineers to the data warehouse. While every team could wire up its own integrations (and invent its own permissioning and auditing system), it seemed preferable to solve this once and for all for everyone.

To host the service, we decided to use our existing internal administrative tooling platform, which gave us access to identity and permissioning for “free”. We also had familiarity with the mcp-go library, having already used it for other MCP-related functionality in the Sierra platform, so we continued to prefer that over the official SDK.

Though we had a much more full-featured system running locally, we wanted to get it deployed piecemeal. That way we could validate that it worked end-to-end, and also not overwhelm code reviewers with giant pull requests. The state at the end of the week was a gateway service that you could sign into, connect one service, and get access to just one tool: whoami, returning your identity and access level.

Week 2

Services: 6 · Weekly users: a few dozen, allowlisted · Pinecone-authored commits: 7%

We added the first real services this week: proxied access to Linear, Slack and GitHub, along with an internal tool allowing access to our data warehouse in ClickHouse. We also wanted to have “knowledge” tools to allow internal Sierra documents to be searched. While it was tempting to build something quick-and-dirty bespoke for our needs, we could see the fun of that initial experience being replaced by the toil of maintaining a reliable crawling, indexing and ranking system. Luckily Sierra has a whole team dedicated to that iceberg, and it ended up being much better in the long run to spend a bit of time figuring out how to reuse their system.

With the system now actually being useful, we wanted to validate that it would work for more than just the team. Following product management 101 principles, we found a few early adopters, enabled the service for them and set up a #mcp-gateway-users channel to communicate with them. It continues to this day, serving as the primary communication and feedback channel. While the most AI-pilled users will be constantly checking the gateway for new services and tools, most users still benefit from the occasional feature roundup post.

On the agentic development side, as we were fleshing out the system, we kept noticing that coding agents would solve problems at the wrong layer, or not be aware of key system properties. We ended up creating an mcp-gateway.md document to capture these invariants. Unlike traditional design docs or RFCs, it is a “living” document - all major tasks would ask the agent to refer to it and update it when completed. It was a constant battle to keep it high-level enough while still capturing important nuances; even the latest models love to over-explain. Serving as the “curators” for that document has at times felt like our most important contribution.

Giving coding agents a self-verification mechanism is key to having them successfully complete tasks with minimal intervention. This seemed straightforward for this project; after all, what could be more natural than “implement this tool, and then call it when you’re done to make sure it works.” However, we observed that agents love to “cheat” (not surprisingly). For example, given a broken authentication setup, the agent would helpfully read the correct token from the file system or local database and use it instead. At other times, if the MCP server behavior was not fully spec-compliant (and thus the built-in client would fail), the agent would fall back to manual HTTP requests via curl, but still declare success. We thus ended up using “consumer-grade” agents like ChatGPT or Claude for final validation or smoke tests. Their more limited capabilities would ensure they would only use the official functionality.

Week 3

Services: 6 · Weekly users: 12% of the company · Pinecone-authored commits: 10%

The main problem to be solved this week was “cross-customer” data access, or rather how to not allow it. Sierra’s customers entrust us with a lot of sensitive data, and our agent engineers help build many of our customers’ agents, thus they need access to it. A nightmare scenario: what if a coding agent acting on their behalf accesses one customer’s internal operating procedures and then “helpfully” copy/pastes them into another, to save time? While Sierra production systems are carefully partitioned by customer identity, the gateway also gives access to fuzzier sources of data, like Slack channels, internal documents, or ad-hoc analytics. Forbidding their use would negate the benefit of the gateway, so we wanted to find a way to do this safely.

We developed a “tagging” system that observes tool responses and associates them with a customer (if any) and a sensitivity level. It was intentionally designed to be generic; data may come from any system and may not have a well-formed schema. We build up a full audit log of data that was accessed about our customers, blocking attempts to access sensitive data about multiple ones in the same session. To do this efficiently, it is a multi-pass system:

  1. A deterministic phase builds a list of candidate customers the data may be about
  2. A fast model does an initial pass over those candidates to narrow them down
  3. A slower model does a final pass to determine the customer (if any) and the sensitivity of the data

Even with the final pass there are false positives. There may also be a legitimate business reason to look at data across customers, usually in specific departments or for special cases like incident investigations. We therefore allow users to approve this kind of “cross-customer” access, but it happens out-of-band, requires a deliberate user action, and also gets added to the audit log.

With that system in place, we had official sign off to launch the gateway to the entire company. As usage of it started to ramp up, we spent more time building out debugging tooling. While coding agents are happy to make sense of 50K of unformatted JSON or go through noisy logs, some gnarly problems still need a human to look at the data. The integrated MCP Inspector that we added to the gateway and the ability to inspect underlying data structures have saved us a lot of time.

Week 4

Services: 12 · Weekly users: 54% of the company · Pinecone-authored commits: 35%

As usage of the gateway picked up, we started to get a lot of feedback that some official MCP servers were insufficient for the workflows that our employees actually do every day. We thus developed a “REST extension” mechanism, allowing us to augment their tools using the public (or sometimes reverse-engineered) APIs that those services also expose. Conversely some tools provided by these servers were of no interest to us, or were deemed to be potentially dangerous, so we also added a way to block or replace them.

One of the other services that we added to the gateway was Pinecone itself, allowing its sessions to be listed, read, and created. This makes it possible to hand-off work from local coding agents to Pinecone or vice-versa. While the gateway is deeply integrated with Pinecone, it is a separate system and does not mandate its use, no strategy tax here. This kind of flexibility has allowed us to meet users where they are, and also be flexible as tooling evolves. For example, when Claude Design launched it was possible to give it access to real data from day one, instead of needing to wait for the equivalent functionality to be added to Pinecone.

Week 6

Services: 17 · Weekly users: 80% of the company · Pinecone-authored commits: 58%

The sales team within Sierra officially kicked off its “AI acceleration” effort, and the gateway plays a major part of that. This exposure to a new cohort of users brought new challenges. For example, they are much heavier users of email, and the tooling that we exposed through the gateway was pretty limited (turns out plain text email sending feels sufficient to engineers, but is a bit lacking in pizzazz to everyone else). Being responsive to their feedback (turning around feature requests within a few hours in some cases) was valuable in retaining those users.

Week 7

Services: 20 · Weekly users: 81% of the company · Pinecone-authored commits: 36%

At times development on the gateway reminds us of the early days of web development. Just as it was a guessing game as to whether the same HTML would work in both Netscape and Internet Explorer, we would struggle to get the full gateway capabilities working in Pinecone, local coding agents and hosted ones. We encountered divergent behavior in session reuse, heartbeat expectations, tool name validation, and other edge cases. Quality time spent in the MCP client and extension compatibility matrix pages also triggered flashbacks of caniuse.com. Luckily, it’s 2026 instead of 1996, and agents are very good at debugging all the flavors of OAuth, so it’s not a huge time sink, but it does feel like this iceberg at times.

Many of these investigations happened this week, explaining the drop in the percentage of Pinecone-authored commits. At this time, one of its limitations was that every agent had a “blank slate”, leading to a lot of toil to connect MCP services and recreate a realistic setup for every coding session. Shortly after this week Pinecone got a persisted “devstash” that allowed pre-configured data to be quickly loaded (and persisted if desired). This allowed gateway development to be more done through Pinecone, lowering the barrier to entry. The goal is to have a fully agentic loop: a user can send a “@Pinecone can you add a gateway tool to…” Slack message and then have it available to use a short while later.

Week 8

Services: 24 · Weekly users: 84% of the company · Pinecone-authored commits: 67%

This week we made a concerted effort to have the gateway more completely replace existing production investigation use cases. Those centered around tooling like Grafana and OpenSearch, which didn’t neatly map into our model - their MCP servers are meant to be self-hosted, and the surface area is broad enough that we didn’t want to vibe-code replacements to run as custom tools. Additionally, we need them to provide data for each cluster or region that Sierra runs in. We ended up giving up some of the architectural purity of the gateway, introducing two new subsystems:

  • Sidecar services, requiring a local MCP server to be run as another process next to the gateway.
  • Multi-region services, where we run multiple instances of each service, one per region.

While this did add operational complexity to the gateway, we hid it from clients - they’re not aware of the “sidecar” distinction, and regions manifest themselves as an injected region parameter to tools, instead of introducing a new concept.

The other use case that was discovered as part of this sweep was the need for “service accounts” - automations are increasingly agent-driven, and we want them to have their own identity instead of using a specific user’s. We generalized the gateway’s “user” concept into a “principal”, allowing both users and service accounts to get the same auditing and debugging capabilities.

Week 9

Services: 26 · Weekly users: 85% of the company · Pinecone-authored commits: 78%

MCP is not the answer to everything. For example, many workflows end up needing access to data from GitHub, and its full-featured MCP server was one of the first that we exposed through the gateway. However, it ended up being a somewhat awkward fit. Agents would spend a lot of time discovering its hundreds of tools, and large responses would bloat the context window.

As an alternative, agents are very familiar with the gh CLI, having encountered it a lot in their training. It also provides more efficient access to the same data – the output can be filtered or piped to a file for later processing. We had initially been wary of exposing the CLI to Pinecone sessions; we want all write or destructive operations to be tied to user intent and approval. We came upon the compromise of having Pinecone mint a separate GitHub token that only gives read-only access to specific repositories, and giving that to the agent to use when invoking the gh CLI. This lets it work with familiar tools, but in a safe way.

Week 11

Services: 32 · Weekly users: 88% of the company · Pinecone-authored commits: 69%

We got an influx of SaaS connection requests this week, and the operational overhead of setting up and making sure they work is getting to us. They are sometimes services that we don’t use ourselves, so even if we configure the connection, we don’t have a good way to validate that it works correctly end-to-end. We ended up introducing the concept of “service owners” - allowing us to federate out this task to folks who actually understand how they’re meant to be used.

Pinecone adoption within the company has also hit an inflection point where the self-service agentic loop that we wished for a while back is now happening more frequently. This week it was a whole service: Google Tasks. We had a power user who really wanted to have it accessible via the MCP gateway. Given their passion and subject matter expertise, their prompting for which tools to implement was a lot better than anything we could have done on the team.

Agentic development is also making it easier to iterate on tool design. For our candidate tracking system we ended up going through four separate implementations this week, since it took us a while to strike the right balance of tool count, flexibility and flexible permissions. With Pinecone writing most of the code, it didn’t feel too bad to throw it away and start from scratch.

Week 13

Services: 40 · Weekly users: 86% of the company · Pinecone-authored commits: 67%

While it’s great that users are contributing more and more services and tools to the gateway, there’s still value that we’re adding to make sure internal services are exposed in a safe manner. One heuristic we have is that the best way to make sure that an agent can’t do something unexpected with sensitive data is to avoid giving it that data in the first place.

This was exemplified by a request we got this week to allow querying of how journeys are used by our customers, to allow an analysis of common patterns. The straightforward approach would be to add a get_customer_journeys tool, allowing any agent direct access to the full content for any customer. The data would get “tagged” as being about that customer, but it seemed sensitive enough that we should have additional safeguards, or find an alternative if possible.

What we ended up adding instead was a get_customer_journey_summary tool, which an agent can use to get an overview of a journey. The gateway handles this one customer at a time, first validating that the summarization “question” is safe (it uses a separate, single-tasking model to rewrite the question in its own words, to ensure it is benign and not requesting sensitive details). We then return that summarized information to the calling agent, which can use it without ever having accessed the raw data.

Today

Services: 45 · Weekly users: 89% of the company

The gateway has become what we hoped: plumbing. The surface is still “visit one page, connect what you use”, with the iceberg underneath staying submerged unless you go looking. None of the individual pieces are exotic, it's the accumulation of a long tail of services and hopefully pragmatic decisions.

We like to think that part of the gateway’s success is due to our focus on actually going to the depths of that iceberg - unlike the usual 80/20 heuristic an automation tool that only covers 80% of a user’s needs rounds down to 0% - it needs to support the full workflow (or be end-user extensible), otherwise they won’t get most of the gains from it.

What has been more surprising has been how community-owned the gateway is: 33 people have contributed code. In July nearly two-thirds of commits came from outside the two of us who nominally own it, usually from someone prompting Pinecone to add the tool they needed. We’re now releasing the lock.

Weather Text Work Location Mode #

“The coldest winter I ever spent was a summer in San Francisco.” — Mark Twain

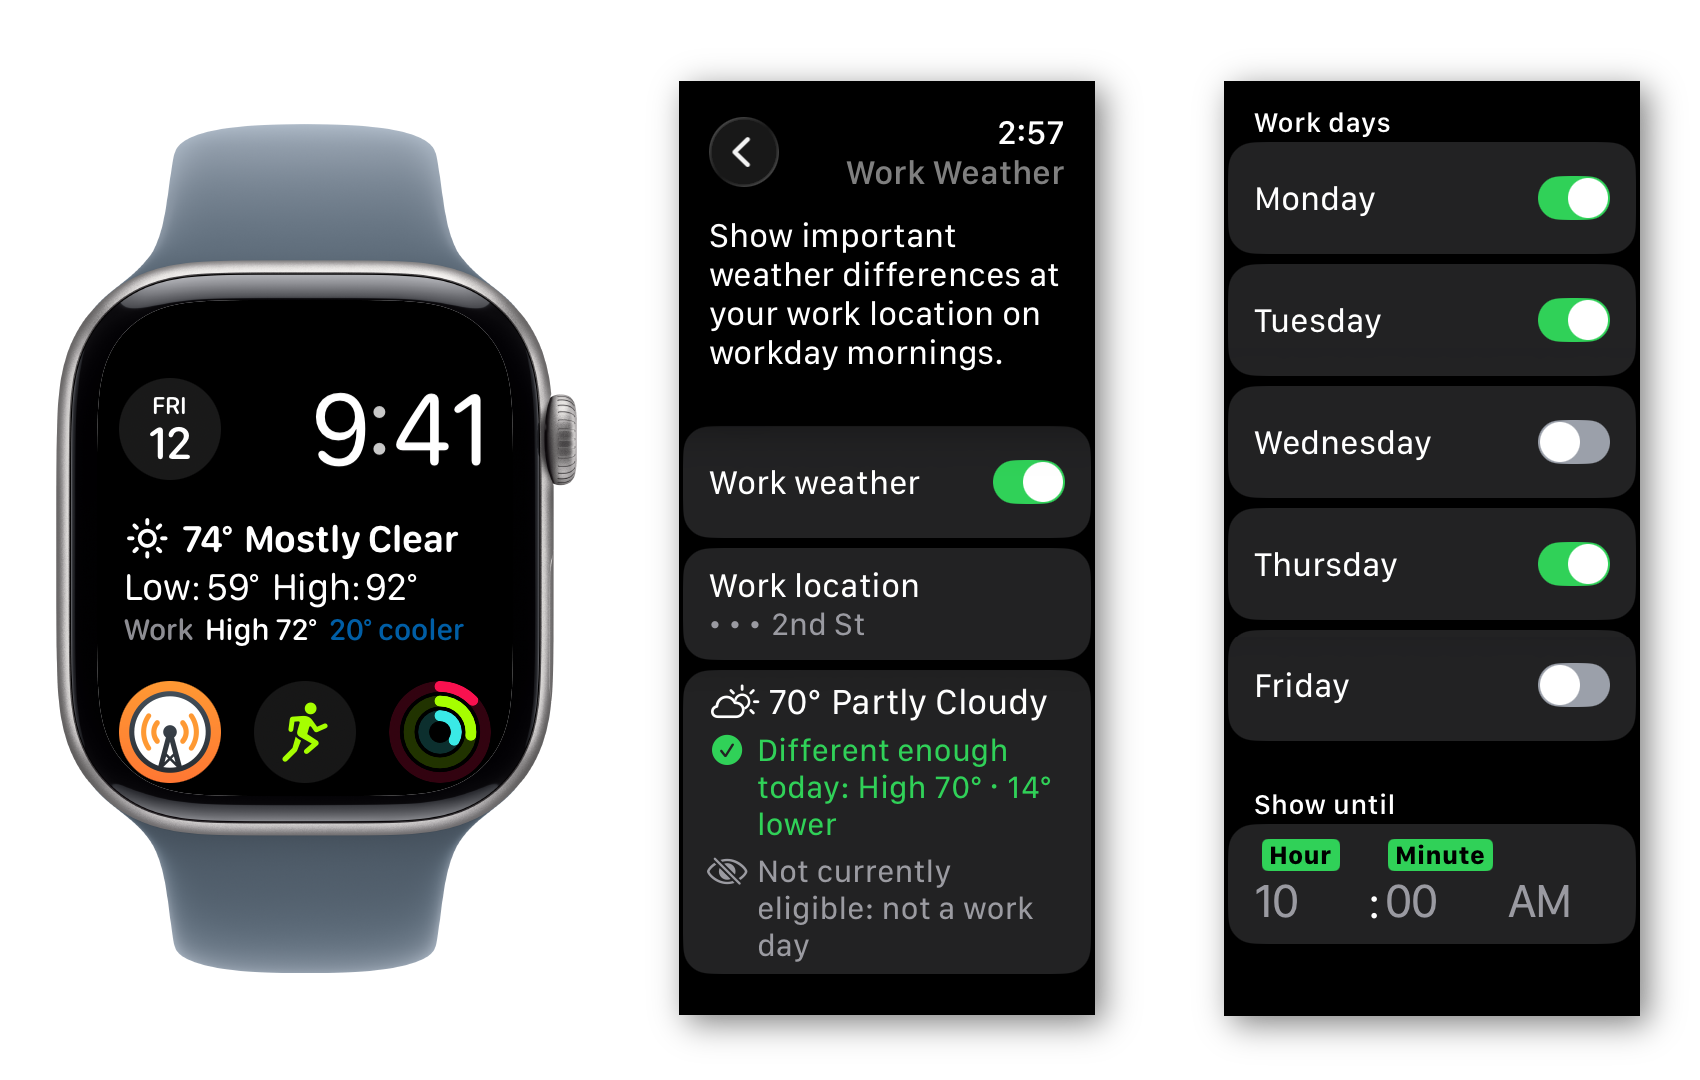
While Mark Twain did not actually say that, I do share the sentiment - I commute into the city (from Cupertino) 3 days a week, and every summer there are days when I realize I am underdressed for the temperatures that await me. I have long wanted to add a “work location” mode to Weather Text, my bespoke weather app. The tedium of coding the configuration UI had always put me off the idea, but it’s now mid-2026, which is a different development era than mid-2024, when the app originated1. Prompted by a recent heat wave, I had a conversation with Codex and ended up with pretty much what I always wanted:

Weather Text work mode screenshots: watch face with complication showing a 20 degree difference between home and work, and the settings to configure work mode

It turned out Codex missed some edge cases and a bit of visual polish, but the feature has been working for me pretty much as intended.

With the app getting this bit of polish, I figured I should capitalize on my momentum and actually publish it to the App Store. Doing a TestFlight build every 90 days got old after the first few times. Worse, I’d occasionally forget, and it would take me a while to notice (the failure mode is a stale complication on the watch face, and the weather around here does not change often).

My rationale for having it be TestFlight-only was that I didn’t want to accidentally end up over the free WeatherKit quota. But the other thing that’s different in 2026 is that the flood of AI-generated apps means that the average app is even less likely to be installed2. With the weather app segment being especially crowded3 I figured the odds of getting unexpected installs were near zero.

I was prepared for some runaround with the App Store review process, since it uses Apple weather data (which has attribution and display requirements) and needs location access. It’s also a watch-only app, which is a more obscure category (and presumably has fewer reviewers assigned). But so far it’s sailed through both submissions I’ve made.

The upshot is that you can now install Weather Text more directly, but please don’t tell your friends.

  1. When I had to copy/paste coding snippets from ChatGPT with gpt-4o, uphill in the snow both ways. 
  2. Since it was somewhat annoying to track down: source article of that graph, which in turn is based on this paper
  3. Even a direct search for the app name does not find it. 

How I consume Bluesky (and Twitter and Mastodon) #

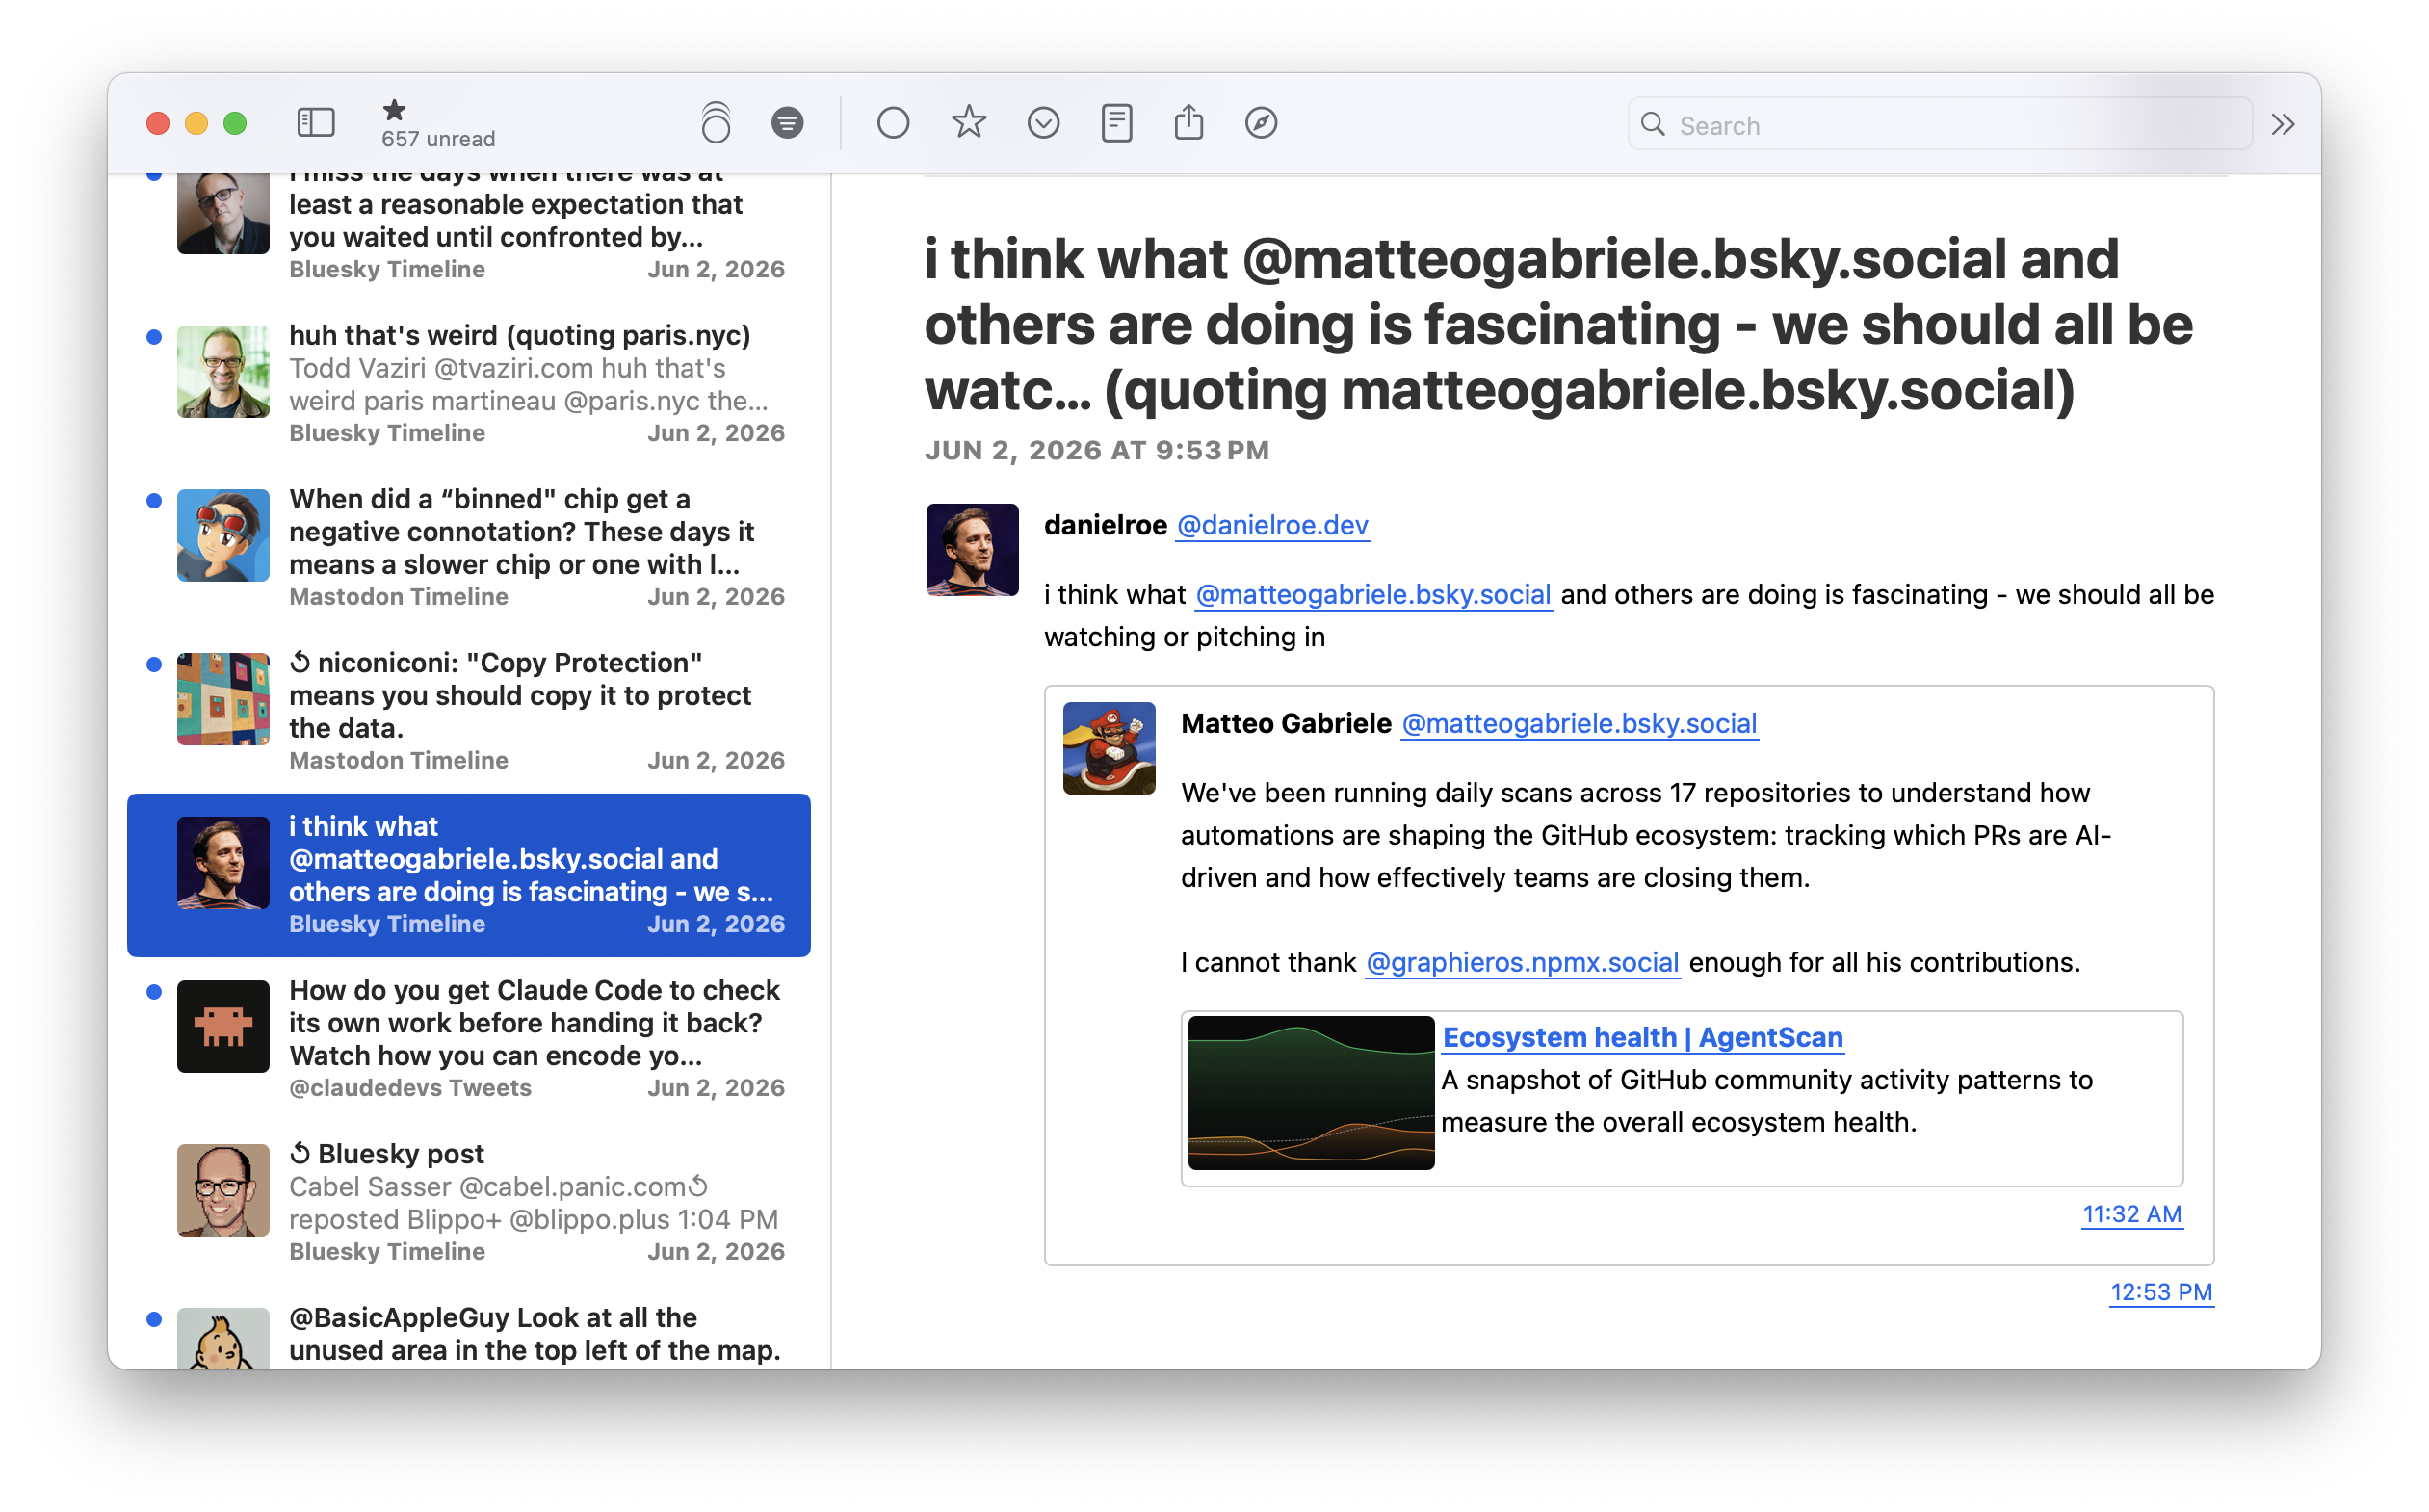
tl;dr: I’ve added Sky Feeder and Tweeter Feeder to join my earlier Masto Feeder tool, allowing me (or anyone else who signs in) to follow accounts from all three social networks in a feed reader.

NetNewsWire showing Bluesky, Mastodon and Twitter posts

In what has now become a trilogy of posts1 I thought I would write up some of the custom tooling that I’ve written to allow me to keep up with Bluesky in a feed reader (in my case, still NetNewsWire). The social network started to take off in mid-2023, and though Mastodon covered my tech/retro interests pretty well, there were some folks (especially wraiters) who had migrated over. I initially used SkyBridge to allow me to treat it as a Mastodon instance in Masto Feeder, eventually moving to my own fork/instance after the shared one got overwhelmed. But the indirection2 and friction when hacking on it3 made it so that it never felt quite right. Some content (like videos) was lost in translation, and the lack of control over the timeline was frustrating - the options were either all replies (including to accounts I don’t follow) or none at all (which filtered out threads). I kept thinking of making my own native tool in Stream Spigot to generate a timeline feed for Bluesky, but the activation energy was too high.

In the meantime, Future Mihai did finally modernize Masto Feeder - in April and May of 2024 I rewrote it from Python 2.74 on App Engine as a SvelteKit app running on Cloudflare Workers. This was a way to both coalesce things on my preferred hosting platform and experiment with a new framework. I made some tweaks since then, but have not had a reason to touch SvelteKit much on this or any other project. Thus the codebase became effectively foreign to me, especially since Svelte 5 introduced runes and made other changes that I had not kept up with. This was definitely a contributing factor to the high activation energy I mentioned above.

Luckily it’s now 2026, and GPT-5.5 (in the Codex desktop app, combined with Context7) is a more qualified SvelteKit programmer than I am or have time to be at the moment. I still have opinions about architecture; for example I directed it to do some preparatory refactoring to share display code with Masto Feeder. The Codex reviews also gave me some additional confidence that I was on the right track, and so Sky Feeder was born. It generates an Atom feed from your Bluesky timeline, publishing it under a “secret” URL that can be used with any feed reader.

The only thing that was missed in the initial Codex-authored PR was how concurrent OAuth token refreshes should be handled - it turned out that serialization was necessary. I doubt that I would have avoided this bug if I had hand-coded everything - it’s the kind of thing that only happens after things have been running in production for a while. Fixing it was also a collaboration with Codex - I had it add additional diagnostic logging and then gave it access to the Cloudflare Observability MCP Server so it could inspect the output and validate the solution.

Empowered by all this, I had Codex build a third tool - Tweeter Feeder for generating a feed for any Twitter/X account. While I had mostly given up on the site, I had been using Nitter’s generated RSS feeds to follow a few people. Nitter is a great service to have around, but it’s quite inflexible5 and even less hackable6. I thus pointed Codex at the Nitter repo, and asked it to reuse the same reverse-engineered Twitter endpoints and auth mechanism for my tool. I only skimmed through the generated code (which has been getting more and more tempting), but it also pretty much worked out of the box, except for some escaping issues7.

Codex also worked out pretty well for more exploratory work. It bugged me that NetNewsWire (possibly due to this change) would show the Stream Spigot favicon for every post, adding redundant visual noise. I had a vague recollection that NNW had some support for per-post images, and Codex validated that the capability exists, but Atom feeds do not populate the avatarURL property of authors while JSON feeds do. It was thus a matter of adding this alternate output mode. Iterating on this was made pretty easy by the Codex remote control feature - it was pretty satisfying to see a bug in NetNewsWire on my phone, switch to the ChatGPT app, find the Codex thread and ask it to fix and redeploy the worker, go back to NNW and see the fix when refreshing the feed.

Stream Spigot homepage showing three tools: Masto Feeder, Sky Feeder and Tweeter Feeder
Stream Spigot: no longer a unitasker

This post came out as being more pro-Codex than I expected. I am also mourning my craft and am not sure how it will all turn out. While I have some general sense of the architecture of this codebase (since the fundamental decisions still date back to the hand-crafted era), I definitely don’t have the same intuition or map of everything in my head that I’ve had with other side projects. I did force myself to fix the escaping issue mentioned above by hand, just to prove that I can find my way around, but we’ll see how long that feeling lasts.

  1. See also 2012’s How I Consume Twitter and 2023’s How I Consume Mastodon 
  2. Bluesky (over atproto) to SkyBridge’s reimplementation of the Mastodon API to my tooling in Stream Spigot 
  3. SkyBridge is a server-side Dart app that runs on Fly.io, neither of which I was interested in learning more about 
  4. 😱 
  5. For example, the entire tweet goes into the feed item title, which worked in the days of 140 characters, but not in today’s world of think pieces disguised as tweets 
  6. I had somehow never heard of Nim before this 
  7. That universal constant - I assume the answer to the last question will also contain a wild " 

Infinite Mac: Resource Fork Roundtripping #

One of the frequent emails that I get about Infinite Mac is “I’ve been copying over these files to every mac I’ve owned for the past 20 (or 30 or 40) years, how can I load them into your site?” While there’s been a “The Outside World” drive from the very beginning, all it can do is a best-effort import/export using available browser APIs. Classic Mac OS used resource forks for structured data and stored additional metadata in the file system (where it belongs). Modern macOS still supports all of this, but unfortunately none of that data is visible to web apps – all they can read is the “data fork” of the file (i.e. its raw contents).

This is a long-standing issue – once Macintosh files started to be distributed over the Internet in the mid-90s, they were usually in a container format like MacBinary or StuffIt to preserve this extra data. While StuffIt is still around, having to download a separate program goes against the ethos of Infinite Mac being as easy to use as possible. After some investigation, I remembered that .zip archives created by modern macOS preserve resource forks ("modern" in this case being relative – this feature dates back to 10.3). Specifically they create a parallel __MACOSX directory structure that has metadata and resource forks in an AppleDouble file.

A while back I added detection of such .zip files, which helped with getting data in. More recently, I also switched the .zip files that Infinite Mac generates when exporting to also use this convention, allowing the Finder to expand and reconstruct the full contents. I also wanted to make this feature somewhat discoverable, and I chanced upon an exemption to the “browsers can’t see resource forks” limitation that I mentioned above – when dragging a whole folder into the window it’s possible to read a file’s resource fork via a magic file/..namedfork/rsrc path (sadly there’s no equivalent for the metadata). I used this to show a notification to remind users of the .zip capabilities.

This video shows these features working together – an old app of mine starts out on the modern macOS host – it can be imported, its vers resource edited, and then exported back out (miraculously today’s Finder still displays information based on it).

Odds and Ends

Using the same notification mechanism, I also made the need to click into the window for emulators that use relative mouse movements (DingsuPPC, PearPC, Previous) more discoverable. Thanks to this tip I figured out how to (ab)use GitHub releases to store large files, letting me finally share the Mac OS X disk images I’ve been using. Finally I fixed some longstanding issues with audio playback in some browsers and stuck modifier keys.

Pair Domains Pricing #

I've been using Pair Domains (née pairNIC) as my default domain registrar for 20+ years. It dates back to my using Pair Networks for website hosting (since 1998, and mscape.com still lives there) - this is a spin-off service. The admin UI is not the fanciest, but it has the control that I need, and the (human) support has always been great.

I recently got a renewal notice for a .com domain, and was a bit surprised at the price – $116.35 for 5 years. My mental model is that it should be closer to $10/year. Pair has changed hands a couple of times in the past few years, first sold to Libsyn in 2018 and then to the more mysterious Your.Online in 2024. The latter is effectively a private equity roll-up, and I was curious if the high prices were due to them. Between the Wayback Machine and my email receipts I was able to put together this historical pricing table:

Year Registration Renewal (5 yr) Renewal (1 yr)
2025 $12 $24.49 $26.99
2024 $11 $20 $23
2023 $11 $19.57 $22.88
2022 $8 $16.57 $19
2021 $8 $16.57 $19
2020 $9.77 $13 $19
2018 $13 $13 $19
2017 $13 $13 $19
2015 $19 $13 $19
2014 $19 $13 $19
2011 $19 $13 $19
2008 $19 $13 $19

It looks like Libsyn started this trend, but the new owners leaned into it even more. The increased divergence between registration and renewal feels like an attempt to rely on laziness/intertia. The renewal price I was quoted was slightly less than the above pricing table ($23.27 vs. $24.49) so perhaps there was some attempt at frog boiling for long-timer customers. But in this case I had already been using Cloudflare's registrar for new projects, so I bit the bullet and did the hour or so of ClickOps to get everything switched over. Not the most satisfying way to spend a weekend afternoon, but hopefully this post can be a PSA for anyone else that has been similarly stuck.

Infinite Mac Construction Set #

tl;dr: You can now embed any OS from Infinite Mac into your website, from 1984’s System 1.0 through 2005’s Mac OS X 10.4. There’s documentation for customizing and controlling embedded instances programmatically. As a demo of what’s possible, Infinite Monkey hooks up an emulated Mac 128K to OpenAI’s and Anthropic’s computer-using models, letting the technologies of 1984 and 2025 to finally meet. The instigator behind all this was Marcin Wichary, whose recent Frame of preference article is another showcase of the embedding capabilities.

A Kindred Spirit

Marcin’s articles – with their attention to detail and passion that they convey – have always struck a chord with me, whether they’re about underrated fonts or underrated movies. I’ve also appreciated that he strives for interactivity, from his Google Doodles to his Config talks. A few months ago, Marcin approached me about doing a modern take on his GUIdebook site, something with a story to tell and a way for readers to experience the material first-hand. Specifically, he wanted a way to embed emulated Mac instances in an article, ideally in as seamless of a way as possible.

Infinite Mac was already used by sites like Classic Macintosh Game Demos, DiscMaster, and Macintosh Repository to host runnable custom instances. But those were full-screen experiences and, in some cases, required a custom fork of the site. I wanted the experience to be closer to a YouTube or Google Maps embed – a snippet of HTML that’s easy to drop into any site, but still controllable via query parameters. To enable this, I added a new /embed endpoint that’s better suited to iframing. In addition to hiding the screen bezel and other chrome, it lets the embedding site control the screen resolution, get notified of the screen contents changing, and send mouse and keyboard events to the emulated Mac.

To keep embedded instances lightweight, I added an option for auto-pausing when they’re hidden. This uses both in-page (IntersectionObserver) and cross-page (visibilitychange) signals to pause and resume the emulator. Fortunately, I didn’t need to implement pausing in each emulator – instead I hooked into their input-reading loop and used Atomics.wait to cheaply suspend execution until the “paused” bit is cleared.

There were a couple of surprises along the way. First, while Chrome lets SharedArrayBuffer work in iframes (via the allow="cross-origin-isolated" attribute), this is not yet supported in Safari/WebKit-based browsers. That made my 2021-era Safari workaround newly relevant. It mostly worked, but it assumed a single global emulator instance which in Marcin’s tests had the hilarious effect of making every Mac on the page receive the same input. I added per-instance tracking so that each one gets its own event stream.

Infinite Mac network request waterfalling

Second, Marcin noticed his custom disk images loaded much more slowly than the built-in ones. Some of that was due to them bypassing Cloudflare’s cache, but even when that was enabled, they were slower. It turned out that prefetching – added in the earliest days of the site, when all it ran was System 7 – had become even more important for more modern Mac OS versions. They read a lot more data at startup, and being blocked for 50-100ms for each chunk adds up when they need to get through a couple of hundred. Extending the prefetching to remote disks too (and caching these prefetched chunks via the service worker) shaved a lot of time off booting the Mac OS 8.5 and NeXTStep images from Marcin’s article.

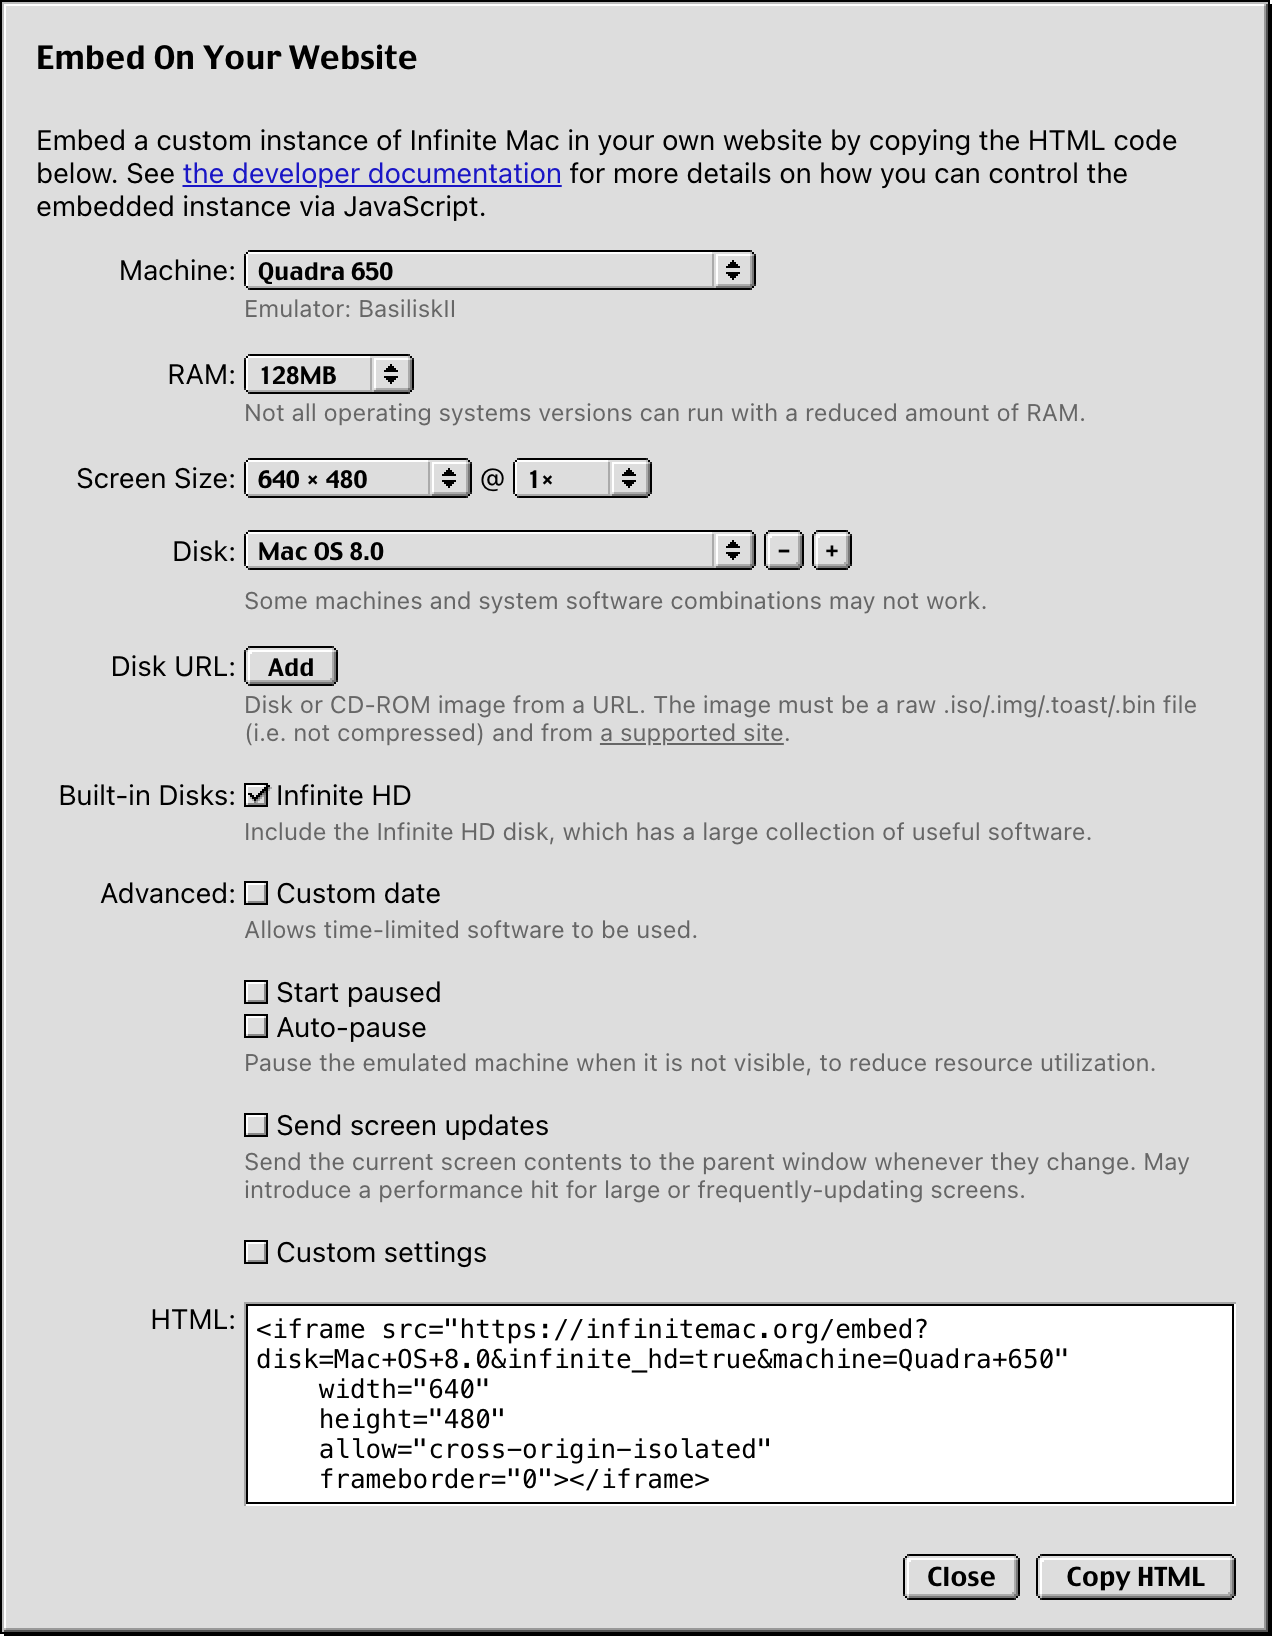
Infinite Mac embed builder dialog

I wanted to make embedding as approachable as possible (well, approachable for those interested in computing platforms from 20 to 40 years ago). There is an embed HTML builder that uses a variant of the custom instance dialog to generate the <iframe> markup for a specific instance (a construction set if you will). I also wrote documentation for the query parameters and message events to control the instance and receive state-change notifications.

Making a Demo Site

Marcin’s article is a kind of demo, and I had a crude testbed, but I wanted to more thoroughly dogfood the embedding support. It occurred to me that its capabilities (get screen content updates, send synthetic input events) made it a perfect fit for the computer use models recently launched by OpenAI and Anthropic. Their demos control a Docker container or other remote environment; having something in the browser is both satisfying (nothing to set up) and safe (the emulation sandbox already limits what the model can do).

The Mac actually has a long history of being controlled by another program, thus the Infinite Monkey site was born (as an aside, the original Monkey desk accessory is installed in the System 1.0 image if you’d like to try it out). Hooking it up was relatively straightforward, the useComputer and useChat hooks have the core glue logic. I even had Claude Code write most of the Anthropic glue code. I went with a “bring your own API key” approach – the models are somewhat expensive, and I did not want the donors to foot the bill. This does make it somewhat less accessible (the OpenAI version of the model is only available for Tier 3 accounts, and possibly not even then). The demo video should help those who don’t have access.

The actual experience of letting an LLM drive System 1.0 is a bit like a dog walking on its hind legs – impressive that it works at all, but objectively a bit underwhelming. The models are slow, it’s definitely faster to use the computer yourself (Anthropic’s own documentation calls this out). They also struggle with the UI conventions of older platforms, especially the press-and-hold mechanics of pull-down menus. OpenAI’s model can’t use them at all, since it can only request click and drag actions. Anthropic’s fares better with its separate left_mouse_down and left_mouse_up, but it often tries to click first, even when instructed otherwise.


OpenAI vs. Anthropic's handling of pull-down menus

This is just one possibility, I’m curious what other things could be built using embedded instances. And if there’s a capability that you wish they had, feel free to file an issue suggesting it.

Odds and Ends

I modernized the site’s Cloudflare setup, adopting both static assets and the official Vite plugin. Both worked as advertised: I have less code to maintain, and the local dev experience is closer to production. It was a welcome change from the usual experience on the frontend dependency treadmill.

The auto-pausing work above also suggested how I might implement a speed setting for more machine types. This fulfills a long-standing feature request to allow older software to run more accurately. It’s somewhat amusing that even in this many-layered environment (an emulator compiled to WebAssembly, which is in turn interpreted or compiled to the native platform) some things can be too fast.

Epilogue: Doctor. Manhattan has nothing on me

  • It is 2006. I am working on making one website (Google Reader) embeddable in another (Gmail).
  • It is 2007. I am working on making one website (Google Reader) embeddable in another (Blogger).
  • It is 2008. I am working on making one website (Google Reader) embeddable in another (iGoogle).
  • It is 2012. I am working on making any web app (Chrome Apps) embeddable in a host environment (Chrome).
  • It is 2017. I am working on making any web app (Live Apps) embeddable in another (Quip documents).
  • It is 2020. I am working on making one website (Quip chat) embeddable in another (Salesforce Lightning).
  • It is 2021. I am working on making one website (Quip documents) embeddable in another (Slack).
  • It is 2022. I am working on making one service (Tailscale SSH) embeddable in another (Tailscale Admin Panel).
  • It is 2023. I am working on making one service (Sierra agents) embeddable in any website or iOS app.
  • It is 2024. I am working on making one service (Sierra agents) embeddable in any Android app.
  • It is 2025. I am working on making one website (Infinite Mac) embeddable in any other.